Pipeline Engine Requirements
The platform needs a pipeline engine. The engine moves data from a Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. to a Data storage. On the way, it can transform the data.
A Pipeline is part of a DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.. A DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. is part of a Data poolData poolA governed, centralized collection of Datasets that are managed together within the Platform. It provides a shared place to organize, discover, and access data, including associated metadata, ownership, and access permissions. With Data pools users can cluster their Datasets according to their organizational structure (e.g., by Departments, Offices).. The engine runs in a Kubernetes namespace with limited rights.
This page gives the requirements. NiFi Usage Concept shows how Apache NiFiApache NiFiA stream processing and connector framework. In CIVITAS/CORE it is the pipeline engine for data integration and transformation (see ADR 047) and implements dataset-defined data flows. satisfies them, and which requirements are still open. ADR 047 records the decision for Apache NiFiApache NiFiA stream processing and connector framework. In CIVITAS/CORE it is the pipeline engine for data integration and transformation (see ADR 047) and implements dataset-defined data flows..
Execution models
The engine must support these execution models:
- Scheduled. A cron expression starts the Pipeline.
- Event-driven. An MQTT message or a webhook call starts the Pipeline.
- Request and response. An HTTP endpoint gives a synchronous answer.
- Batch and stream. The engine must process a large set of records, and also a continuous flow of records.
Connectors
The engine must have a Connector for MQTT, for HTTP and for SQL.
It must also read and write files. Files can be text or binary. The content can be structured or unstructured.
Processing
The engine must do these operations:
- Transform data, primarily JSON.
- Apply a Mapping and validate the result.
- Write to a Data storage: SQL, HTTP, MQTT and other targets.
- Control the flow: if/then/else, switch/case and, if possible, loops.
- Give access to data through an API.
- Handle errors. It must retry, and it must move a failed record to a dead-letter path.
Performance
Scaling
The engine must scale horizontally and vertically. Two properties must scale: the number of Pipelines, and the parallelism of one Pipeline.
Expected volume
These values apply to a large city. Berlin is the reference.
| Parameter | Value |
|---|---|
| DatasetsDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions., total | up to 5,000 |
| Data poolsData poolA governed, centralized collection of Datasets that are managed together within the Platform. It provides a shared place to organize, discover, and access data, including associated metadata, ownership, and access permissions. With Data pools users can cluster their Datasets according to their organizational structure (e.g., by Departments, Offices). | 200 to 300 |
| DatasetsDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. with a Pipeline | approximately 500; the other DatasetsDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. are static |
| Tables per DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. | approximately 4 |
| Rows per table | approximately 250 |
| Users, read only | up to 20,000 |
| Users, administrative | approximately 400, which is 2 % |
| High-frequency data from IoT devices | one message every 0.5 s to 1 s |
Two values are not yet known. The first is the quantity of dynamic DatasetsDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. with sensors in a city administration. The second is the frequency and the volume of IoT use cases.
Resource efficiency
The engine must use resources efficiently. An unused Pipeline must not consume many resources.
Security
Isolation
Each Pipeline is a security domain. The Pipelines of one DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. are in the same domain.
The engine must give three types of isolation:
- User to user. A user must not get access to the Pipeline or the data of a different user without a Permission.
- User to platform. A user must not get access to internal resources of the platform.
- Pipeline to Pipeline. A Pipeline must not get access to a different Pipeline.
Access control uses Roles, Permissions and DatasetsDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.. A Pipeline is part of a DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions..
Confidential Datasets
A confidential DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. needs an explicit release before a different Data poolData poolA governed, centralized collection of Datasets that are managed together within the Platform. It provides a shared place to organize, discover, and access data, including associated metadata, ownership, and access permissions. With Data pools users can cluster their Datasets according to their organizational structure (e.g., by Departments, Offices). can use it. The confidential property must stay visible everywhere.
A planned feature lets the owner of a confidential DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. release it. The release makes a Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. that other DatasetsDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. can use.
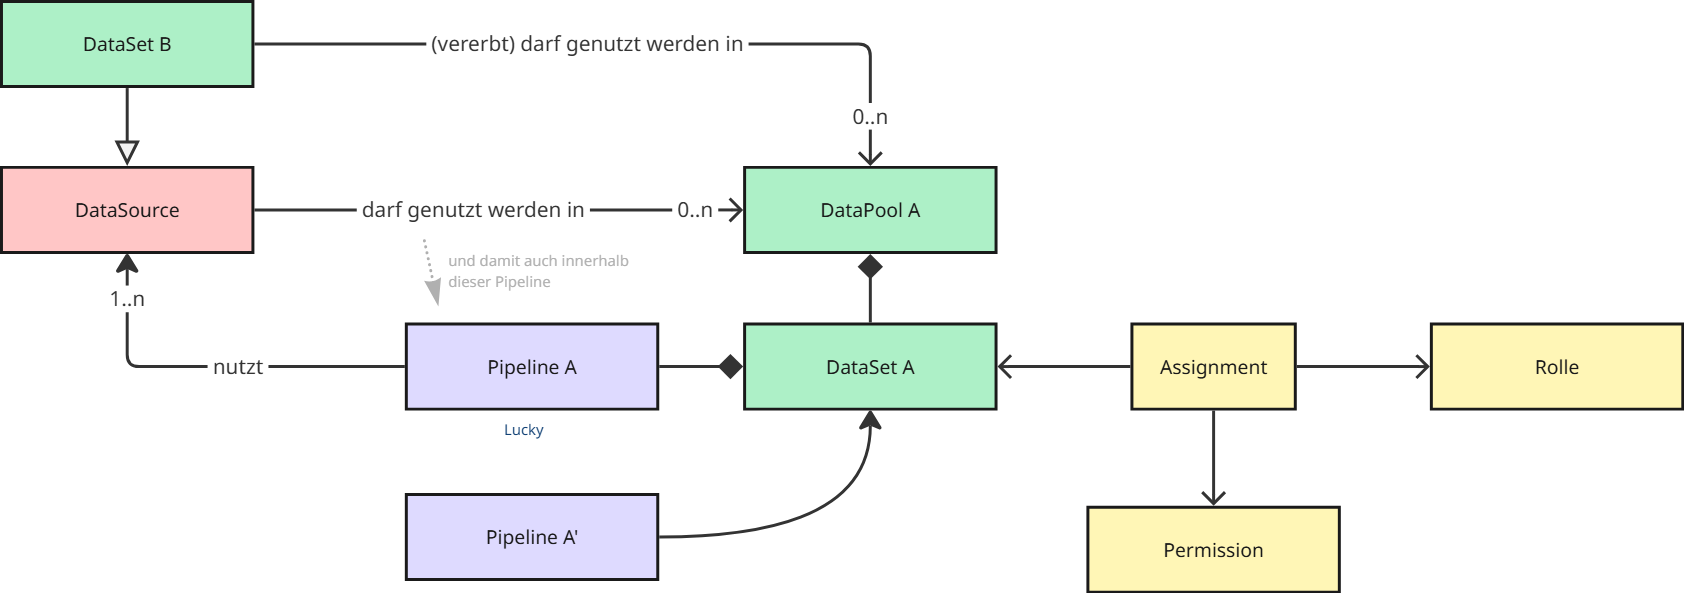
In the example, user Lucky can use DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. B in Data poolData poolA governed, centralized collection of Datasets that are managed together within the Platform. It provides a shared place to organize, discover, and access data, including associated metadata, ownership, and access permissions. With Data pools users can cluster their Datasets according to their organizational structure (e.g., by Departments, Offices). A. This is not sufficient. Lucky also needs a READ Permission for the yellow entities. Two Permissions are necessary: USE between the two green entities, and READ between the yellow entity and the green entity.
Threat model
| Attacker | Example | Classification |
|---|---|---|
| External attacker, not authenticated | Network access to a Pipeline endpoint | Must be prevented. Use ingress rules, network policies and authentication. |
| Authenticated user, read only | Access to the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. of a different user | Must be prevented. Use access control on the Pipeline and on the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.. |
| Authenticated user, administrative | Malicious code in an own Pipeline that reads foreign data | Must be limited. Isolate the Pipeline, or limit the available processors. |
| Platform administrator | Full access | Trusted. This is not a protection goal. |
| Advanced persistent threat | Attack on a weakness in the JVM or in the kernel | Scan the code of script nodes. Give dangerous nodes only to trusted users. |
The third attacker is the important one. An administrative user writes the Pipeline, and the engine runs it. The selected engine must show how it prevents this attack. It can isolate the process, it can remove the dangerous processors, or it can do both.
Operation
- The engine runs in a Kubernetes namespace with limited rights. It must not need a CRD or a ClusterRole.
- Helm installs the engine.
- The engine must run on premises and in an air-gapped network.
- An external registry keeps the versions of the Pipeline definitions.