Persist, transform & provide Data
Role: Data Architect, Data Steward
Goal: You want to build pipelines, transform and persist data, and make it available for consumption through an API.
Required Permissions: create DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions., release DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
What you will achieve
After completing this guide, you will have:
- Created a DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
- Defined and validated a Pipeline
- Created a Mapping
- Defined an API
- Managed optionally access permissions
- Set the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. status to mark it as Ready
Before you start
- Verify that you can create DatasetsDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.. If this option is unavailable, contact your TenantTenantAn isolated organizational partition that owns Data pools, Datasets, Users, Groups, and Roles. All access rules exist within their Tenant, and the Tenant is the widest Scope of a Role. Currently, one Tenant corresponds to the Platform. Admin to request access.
Understand your data flow
Before building a pipeline, make sure you understand how your data flows through the system. In CIVITAS/CORE, data is processed and stored through Pipelines before it can be made available through an API.
This means:
- data is loaded from a Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network.
- transformed step by step
- stored in a storage
- provided through an API
In this guide, we demonstrate how to persist and transform data using this example use case. It shows how master data and measurement data are processed in pipelines and stored as Observations in a SensorThings APISensorThings APIA standardized API based on the OGC SensorThings API specification for accessing time series and IoT data. It enables structured retrieval and management of observations and related entities. backend.
→ You will find additional context from the Smart Meter energy use case in the highlighted boxes throughout this guide.
Requirements
Two types of data are processed:
- Master data → used to create SensorThings entities such as Things and Datastreams
- Measurement data → continuous smart meter values received via MQTT
Pipelines are used to:
- load data from Data sourcesData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network.
- transform and map the data
- provide the data for further use
Make sure you have:
- available Data sourcesData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. for master data and measurement data
→ Before measurement data can be stored, the required SensorThings entities must exist. In this guide, you will build pipelines to process both data flows.
Step-by-step guide
Step 1: Create a Dataset
- Go to DatasetsDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
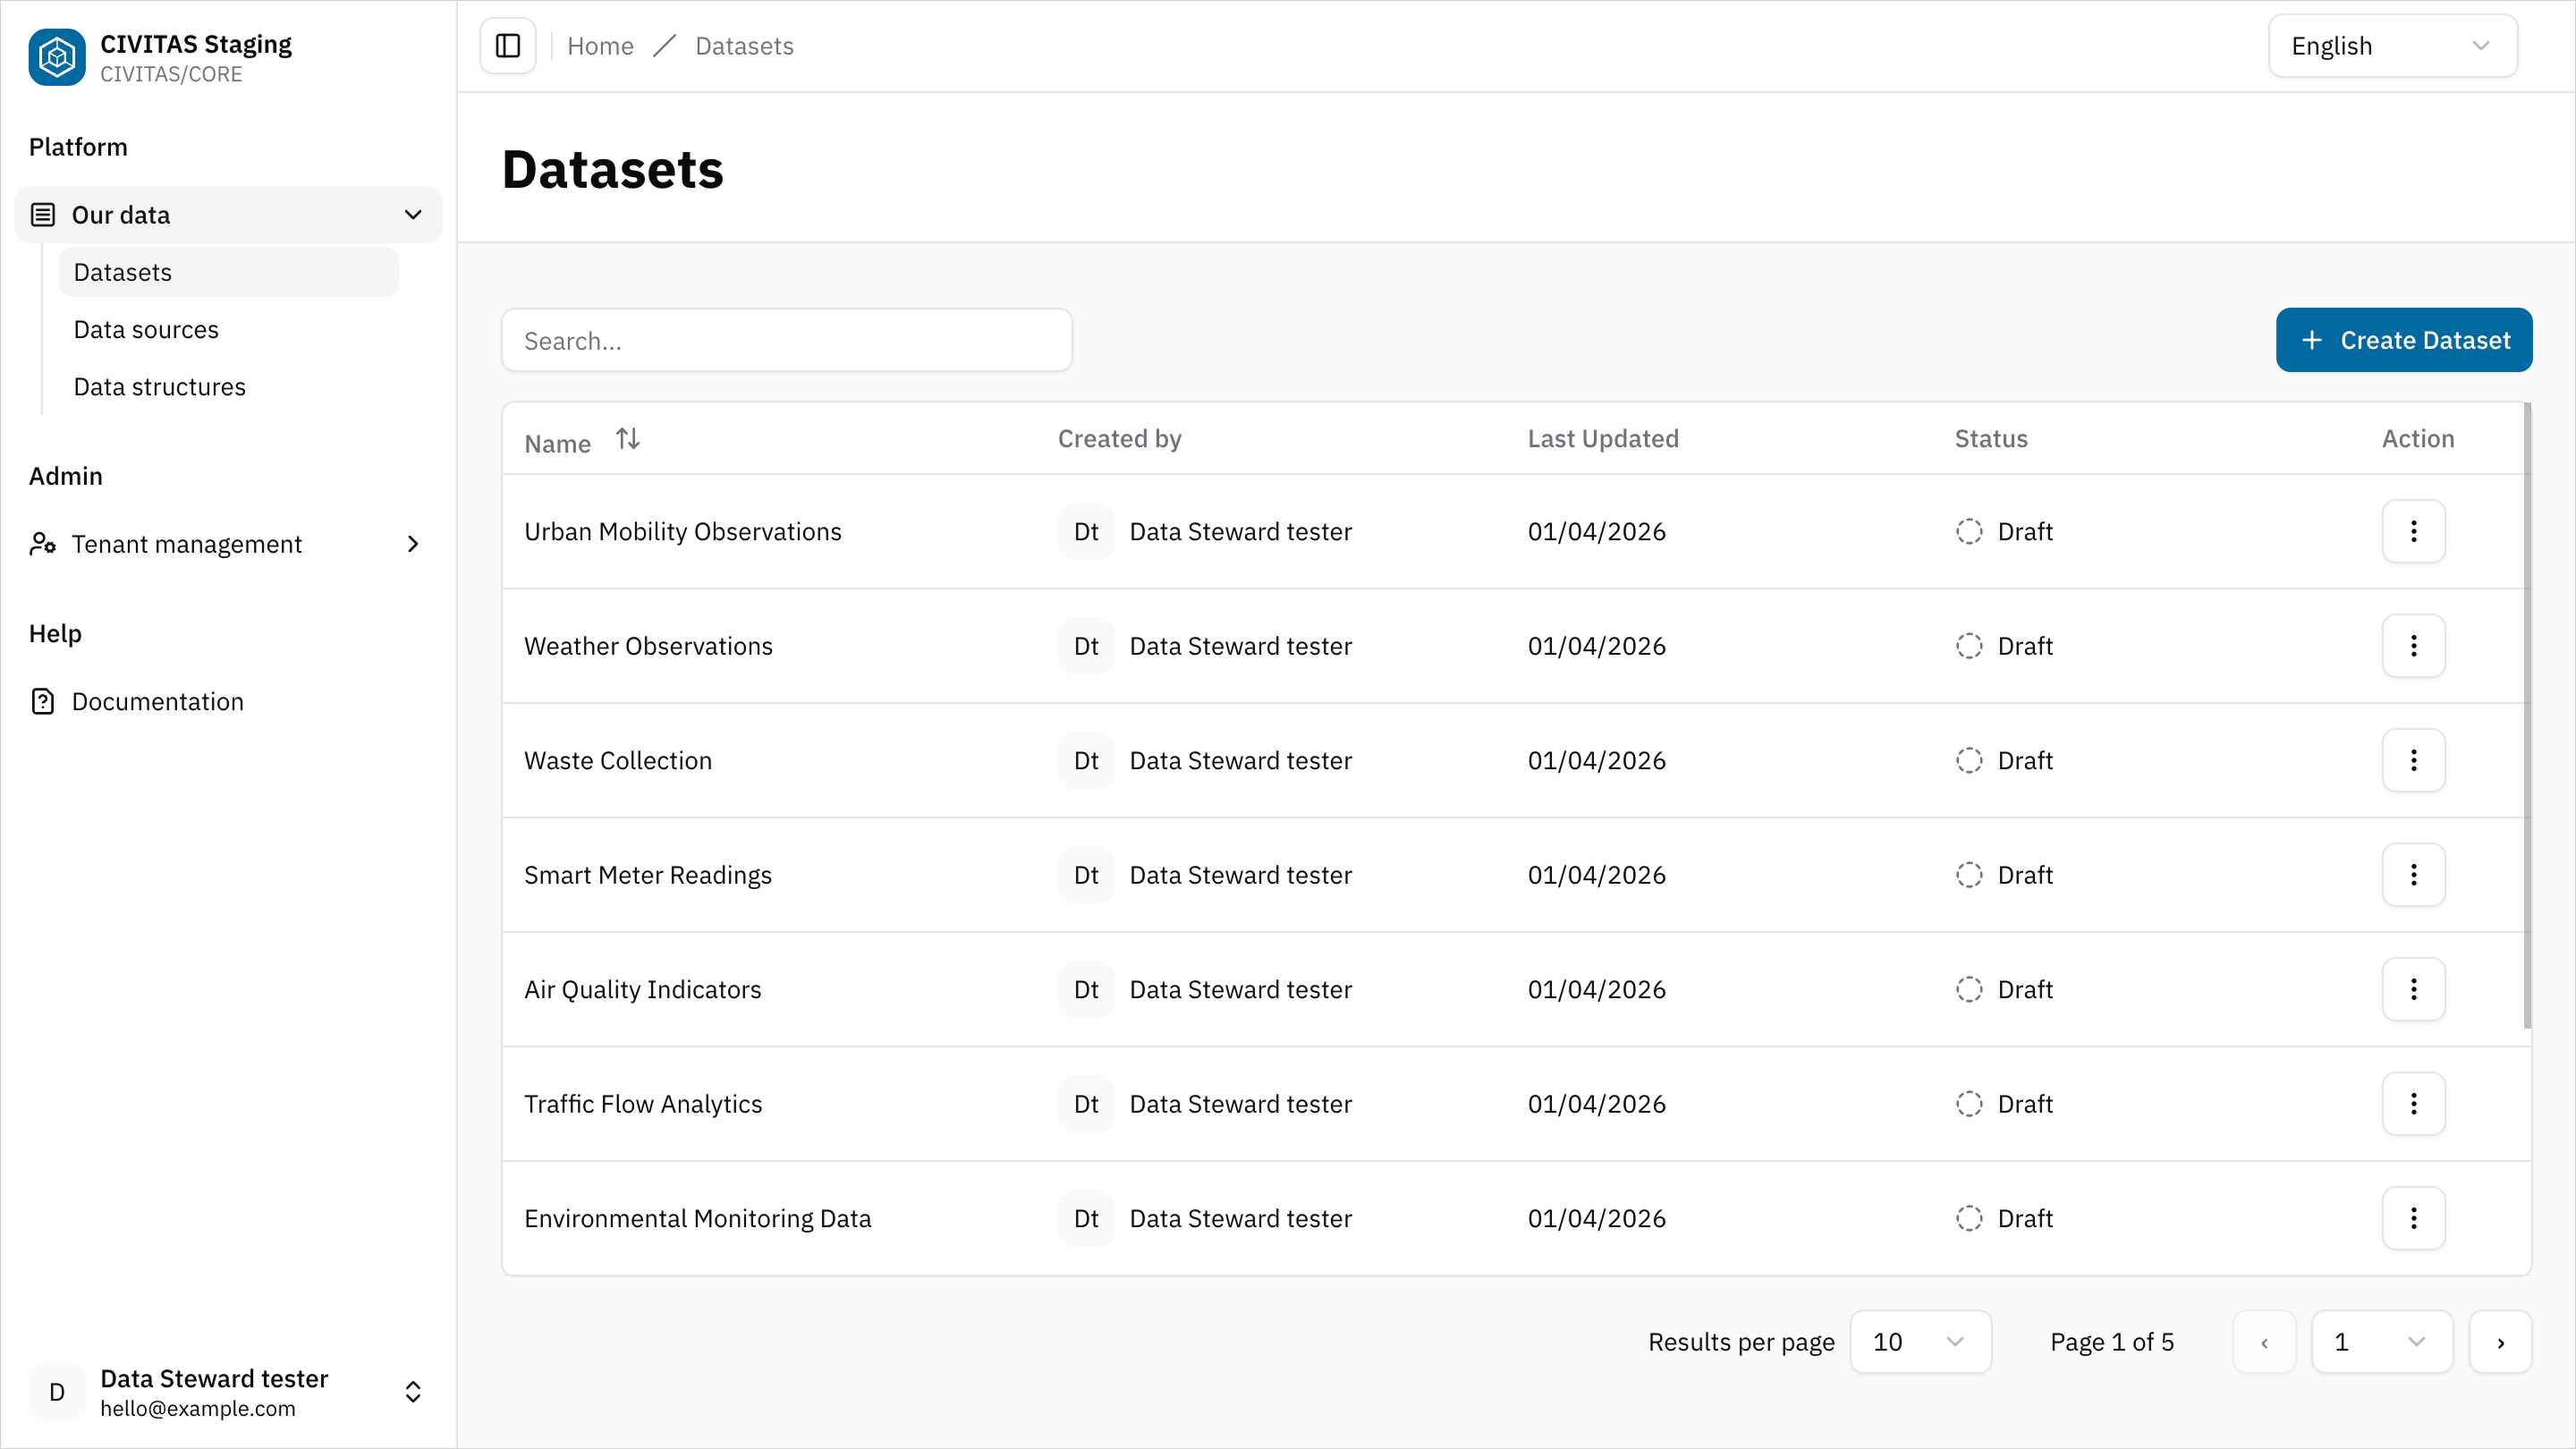
- Click Create DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
- Enter Name and hit Create and continue
- Add Base Information and hit Save
Create a DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. to combine and process smart meter data from different Data sourcesData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network..
Example name:
- Smart Meter energy usage
Step 2: Define a pipeline
→ A pipeline is an automated sequence of steps used to ingest, transform, or store data within the Platform.
- Click Add pipeline in the section Data flow
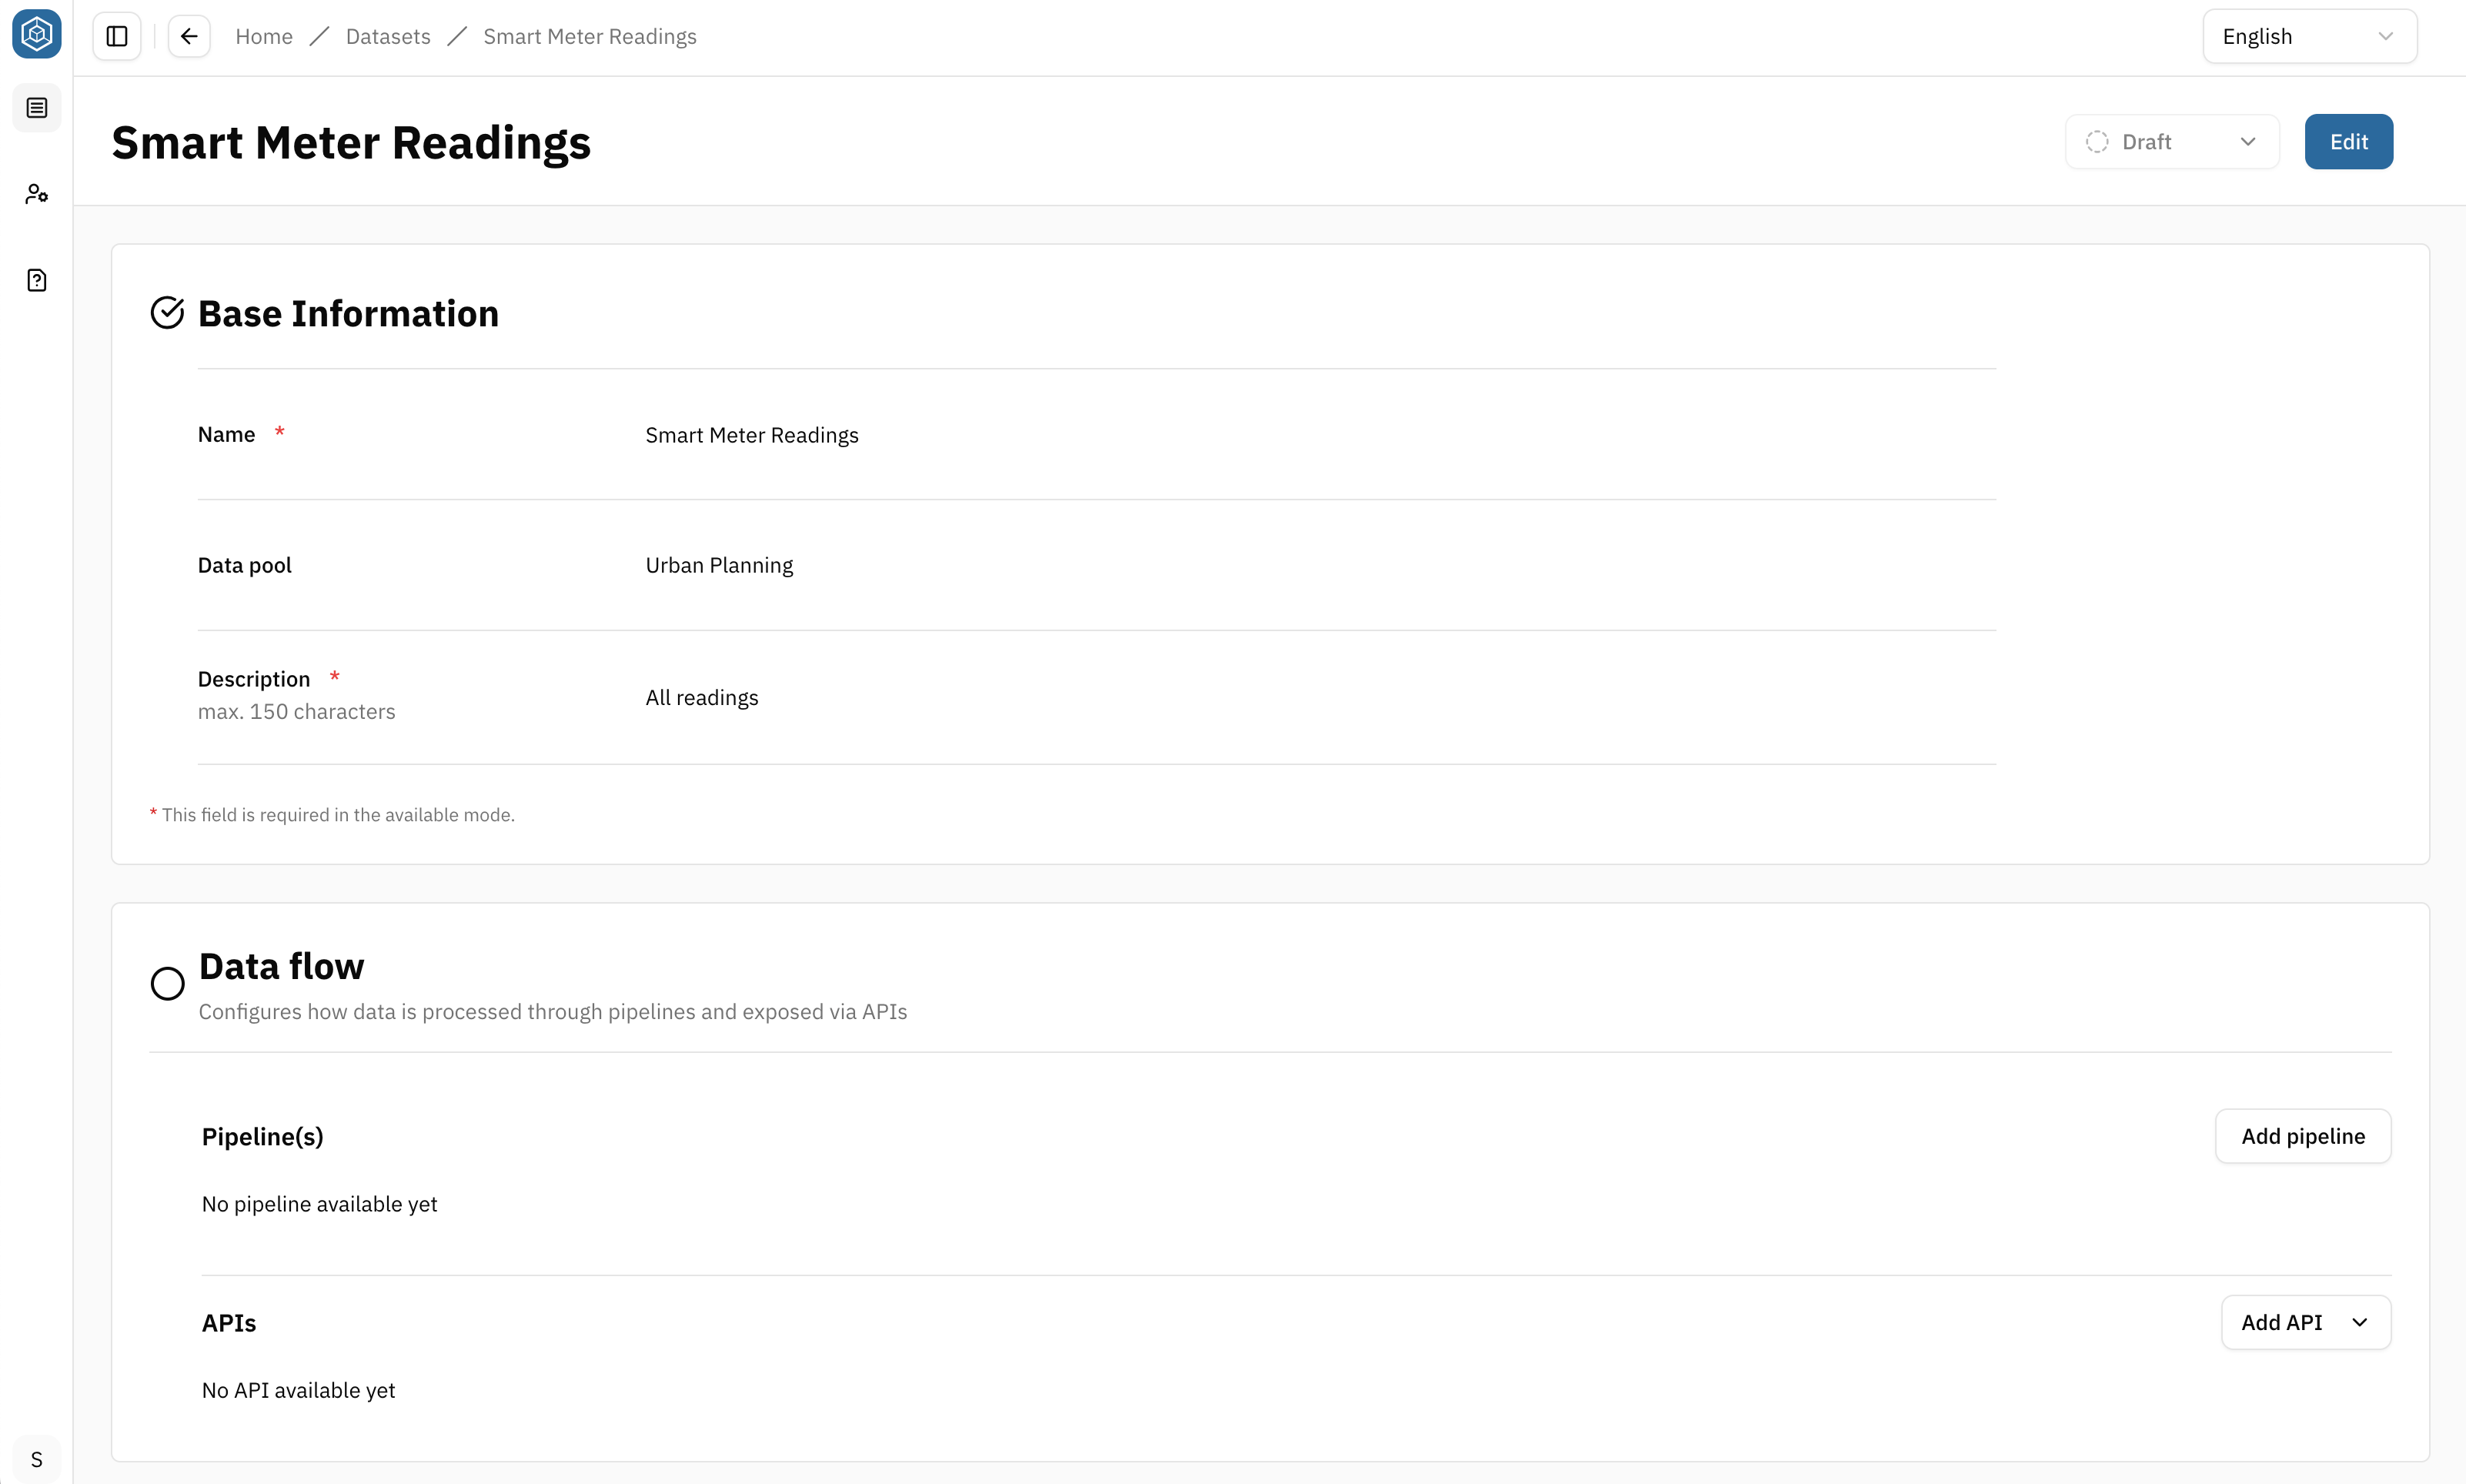
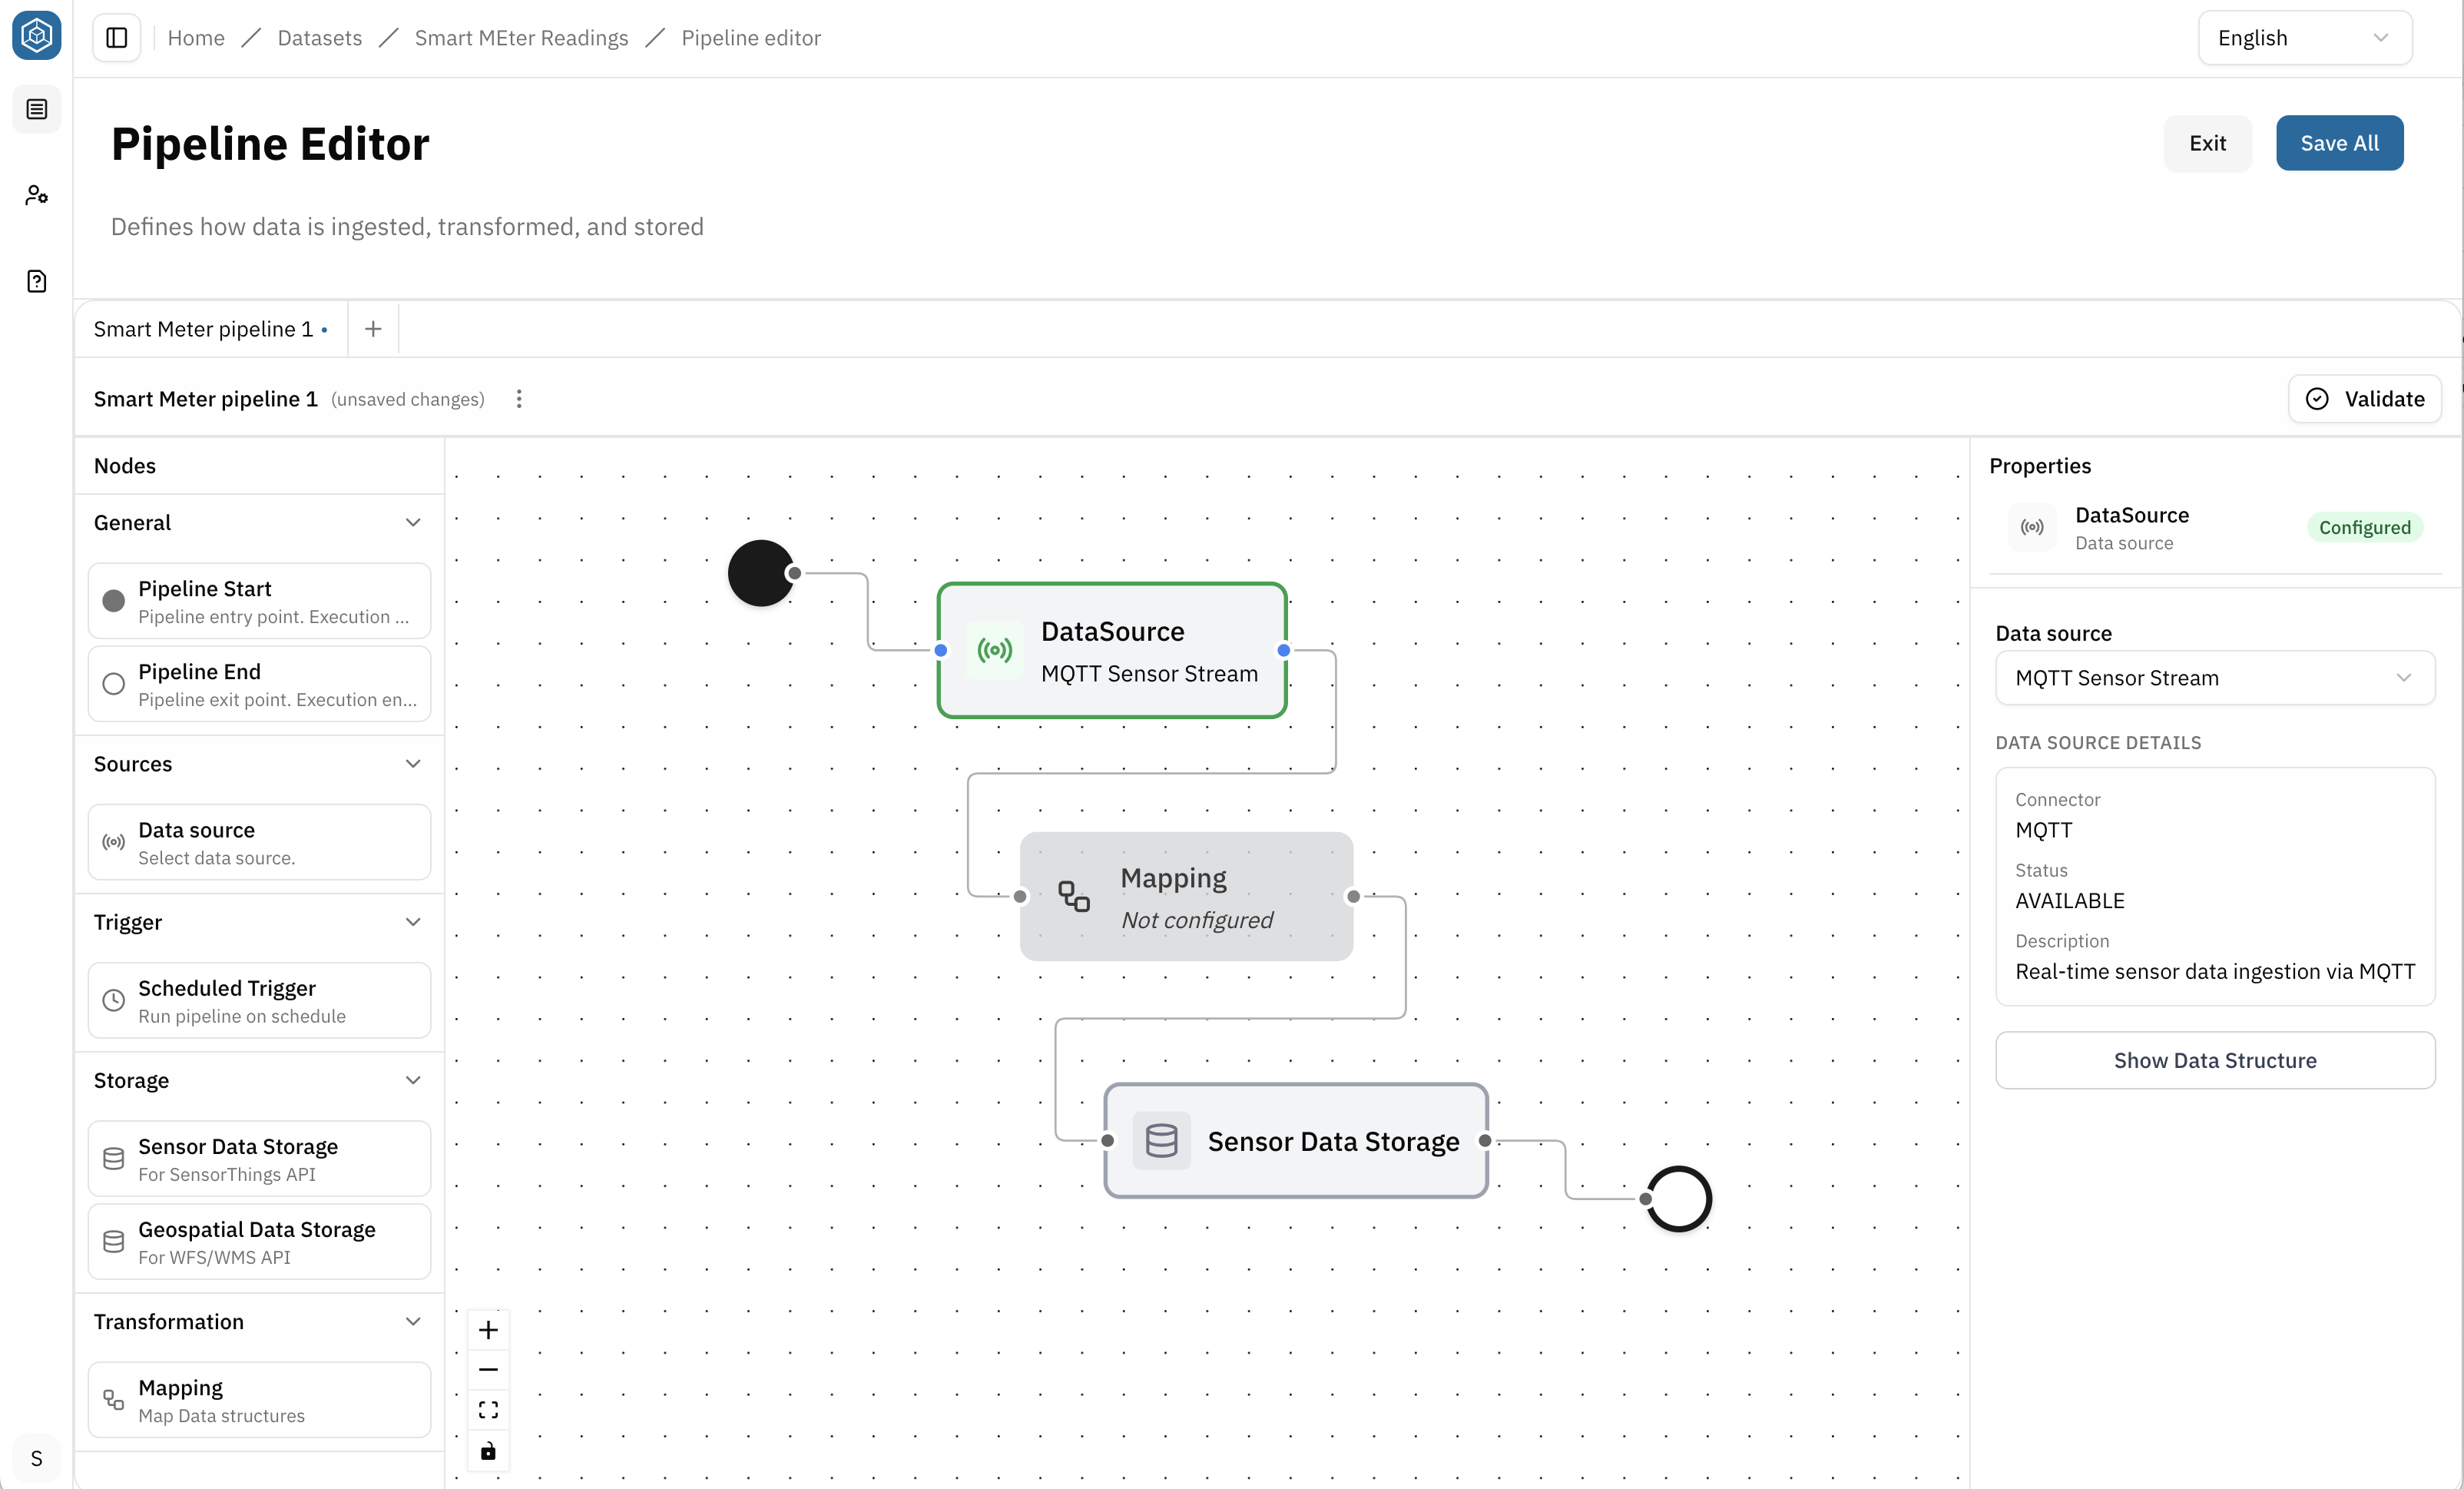
A pipeline is an automated sequence of steps used to ingest, transform, or provide data within the Platform. Pipelines are designed on a canvas-based interface that allows you to work freely. You can add, configure, move, and connect nodes in any order. Nodes and connections can be removed by selecting them and pressing the Delete key on your keyboard.
- Enter a name for the pipeline at the top of the canvas
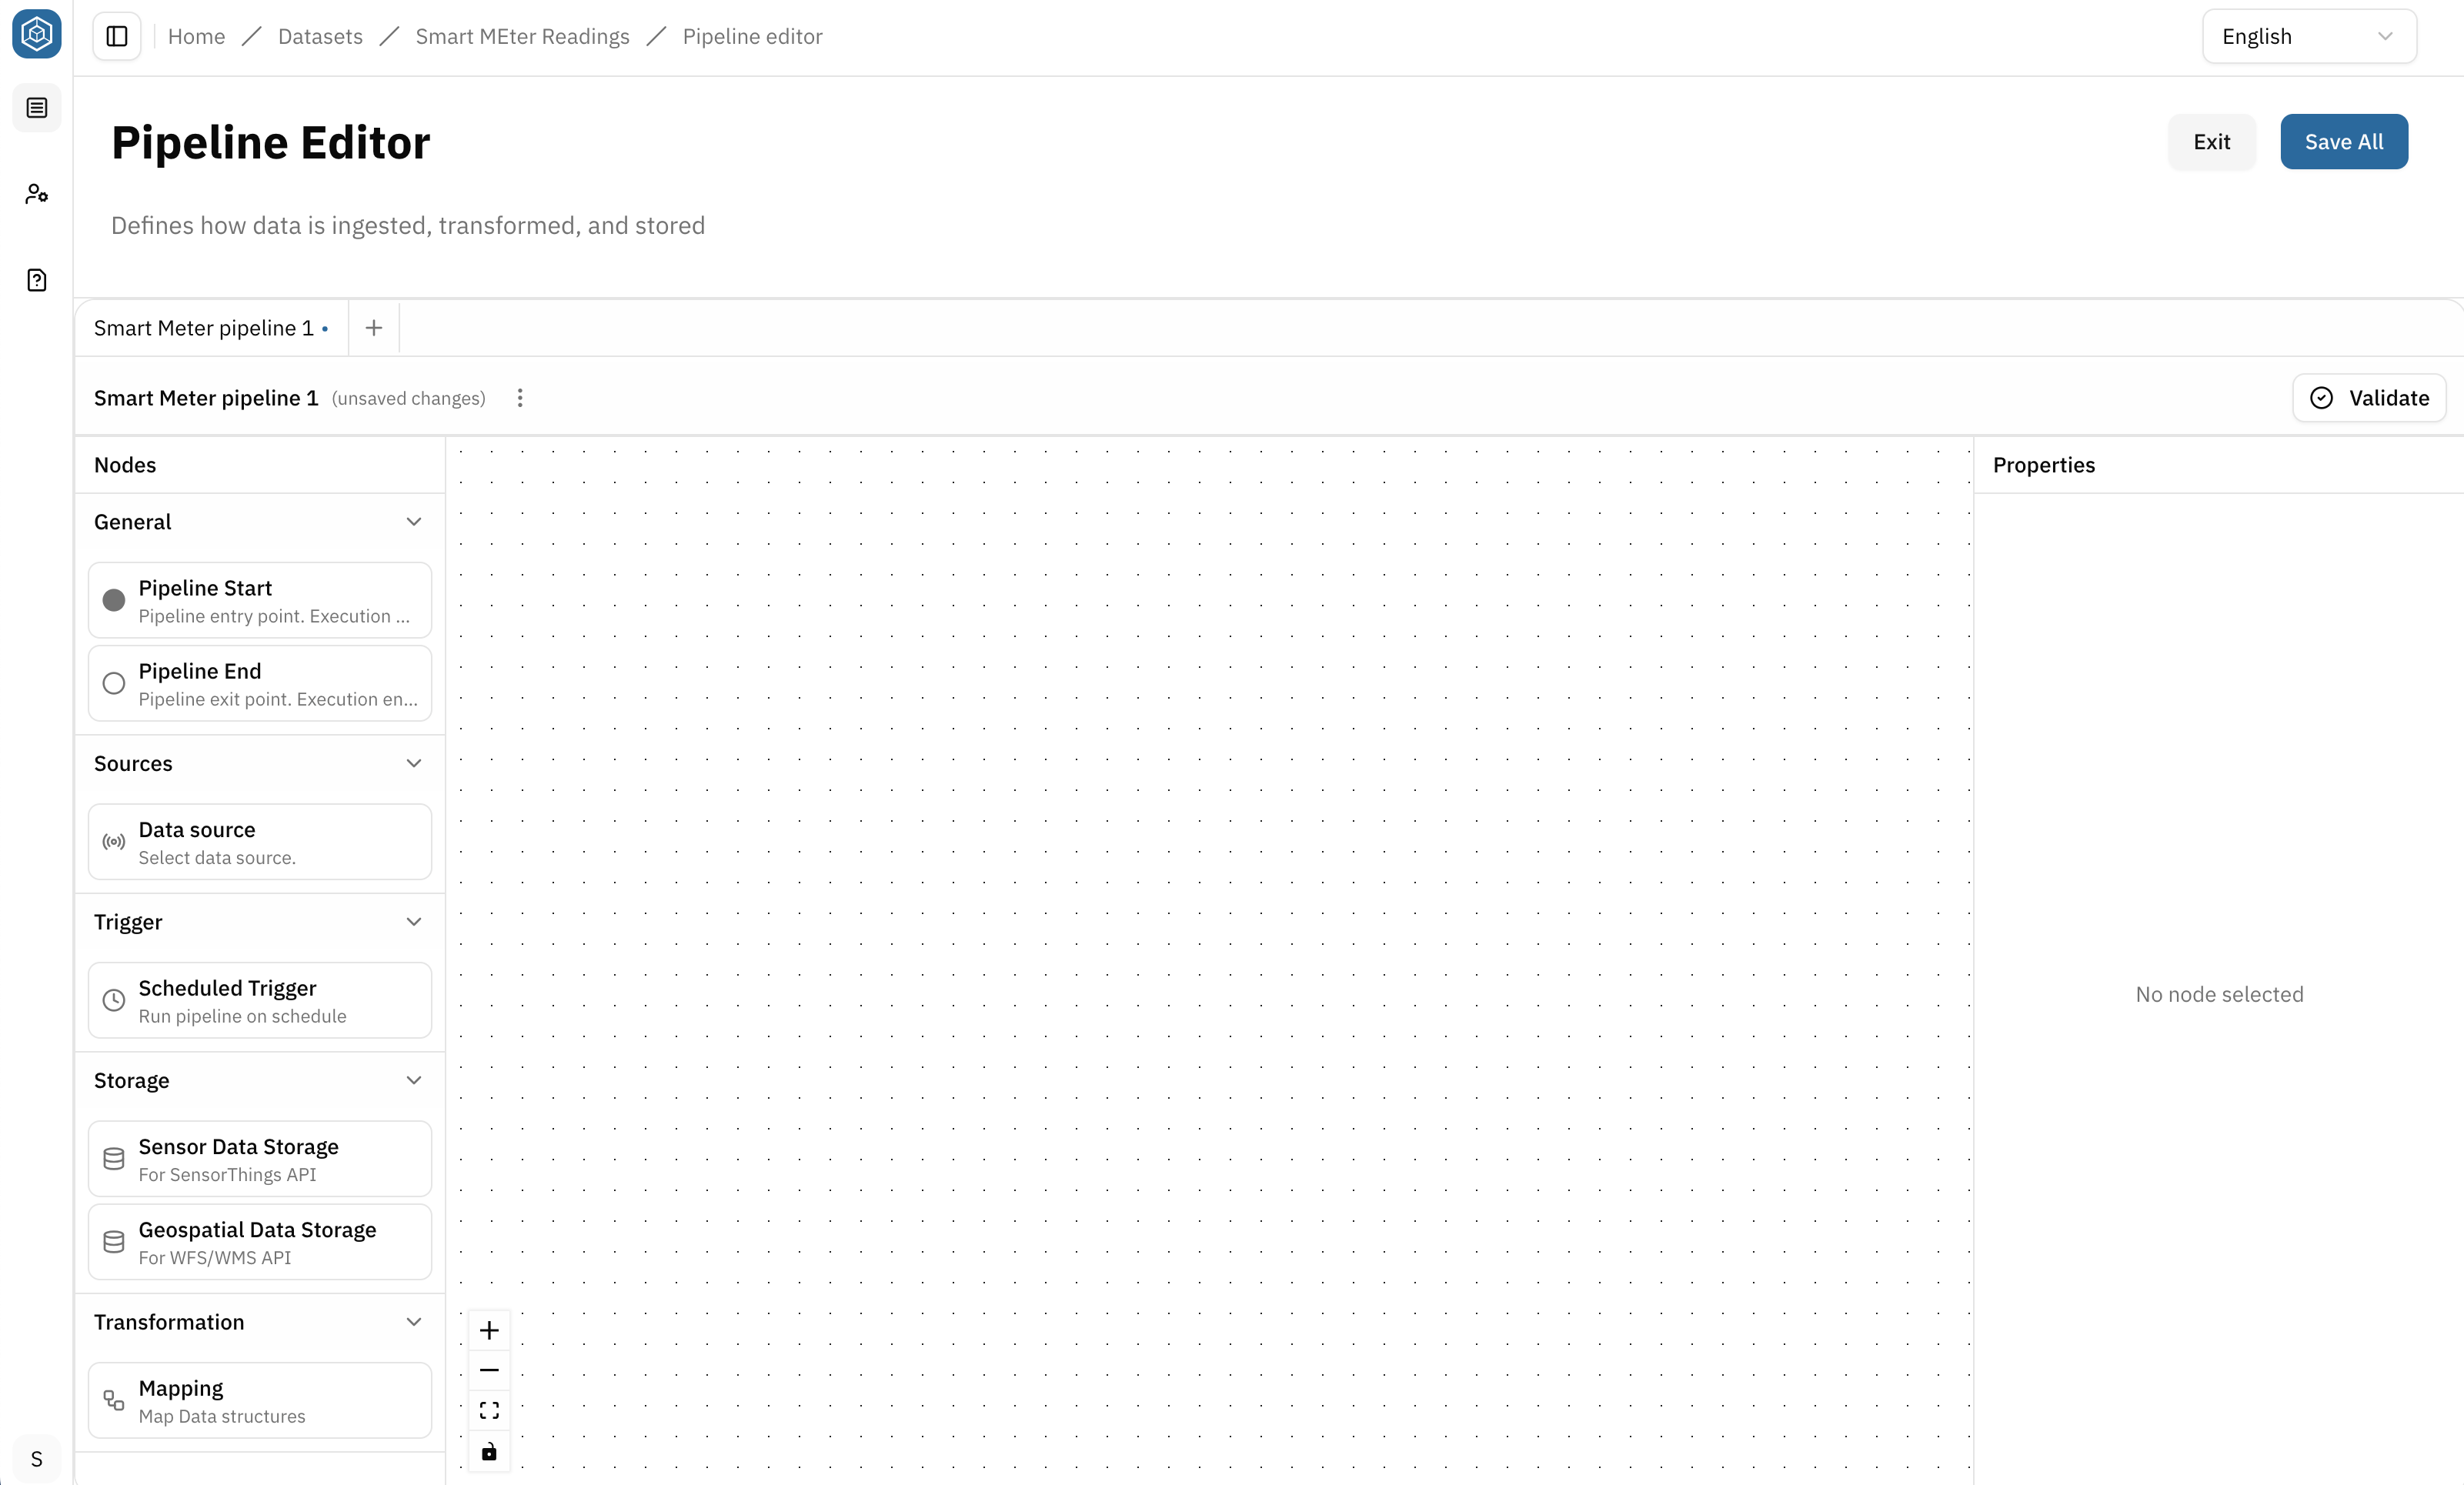
It helps you identify and manage multiple pipelines within a DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
- Add nodes to the canvas
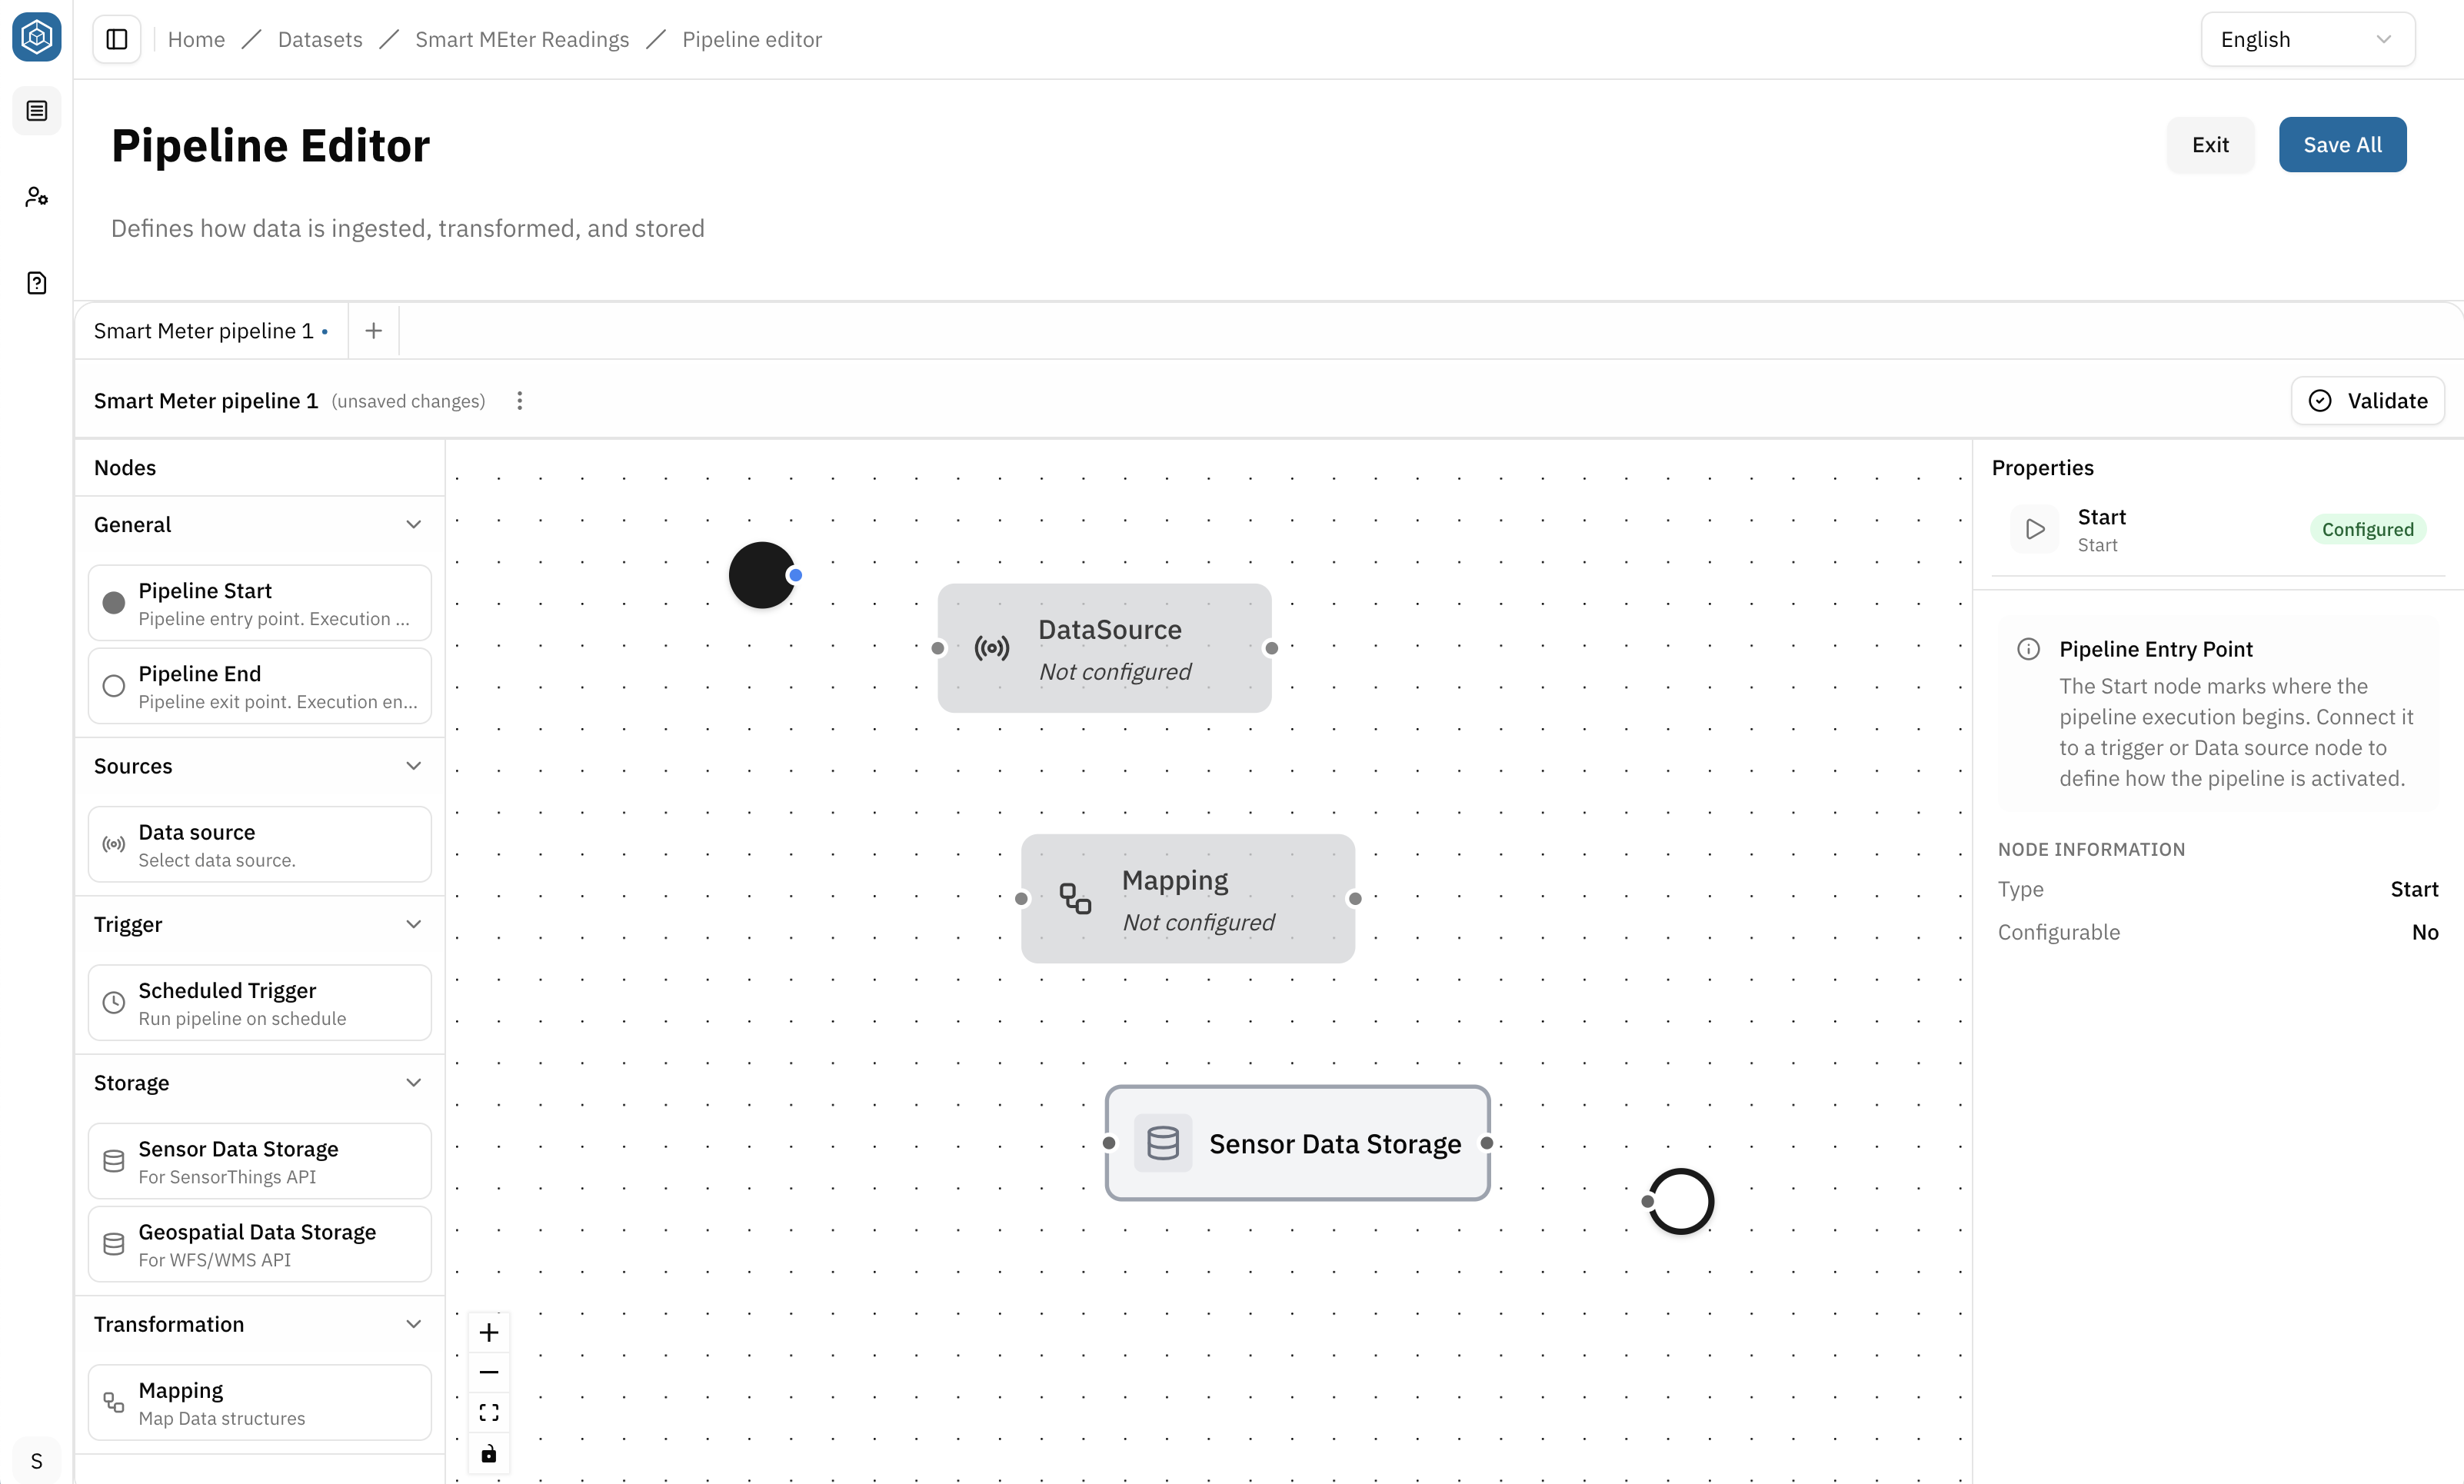
In CIVITAS/CORE, every pipeline has a defined structure:
- a Flow start → marks the beginning of the pipeline
- a Flow end → marks the end of the pipeline
Between these nodes, you define how data is loaded, transformed, and stored.
Pipelines are flexible:
- they can start with a Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. or be triggered by an event (e.g. schedule)
- they can include one or more transformation nodes (e.g. Mapping)
- they can store data in different storage backends depending on the use case
What matters:
- all nodes must be correctly connected
- all required node configurations must be completed
- the pipeline must pass validation
Example pipeline:
- Load and store data: Flow start → Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. → Mapping → Storage → Flow end
- Click on a node to configure it based on your use case
A Mapping transforms data from an input Data structure into an output Data structure.
To create a Mapping:
- Add a Mapping node to the Pipeline
- Select the Mapping node
- Choose an input Data structure
- Choose an output Data structure
- Open the Mapping Canvas
In the Mapping Canvas, you can:
- connect source and target attributes
- apply transformations where required
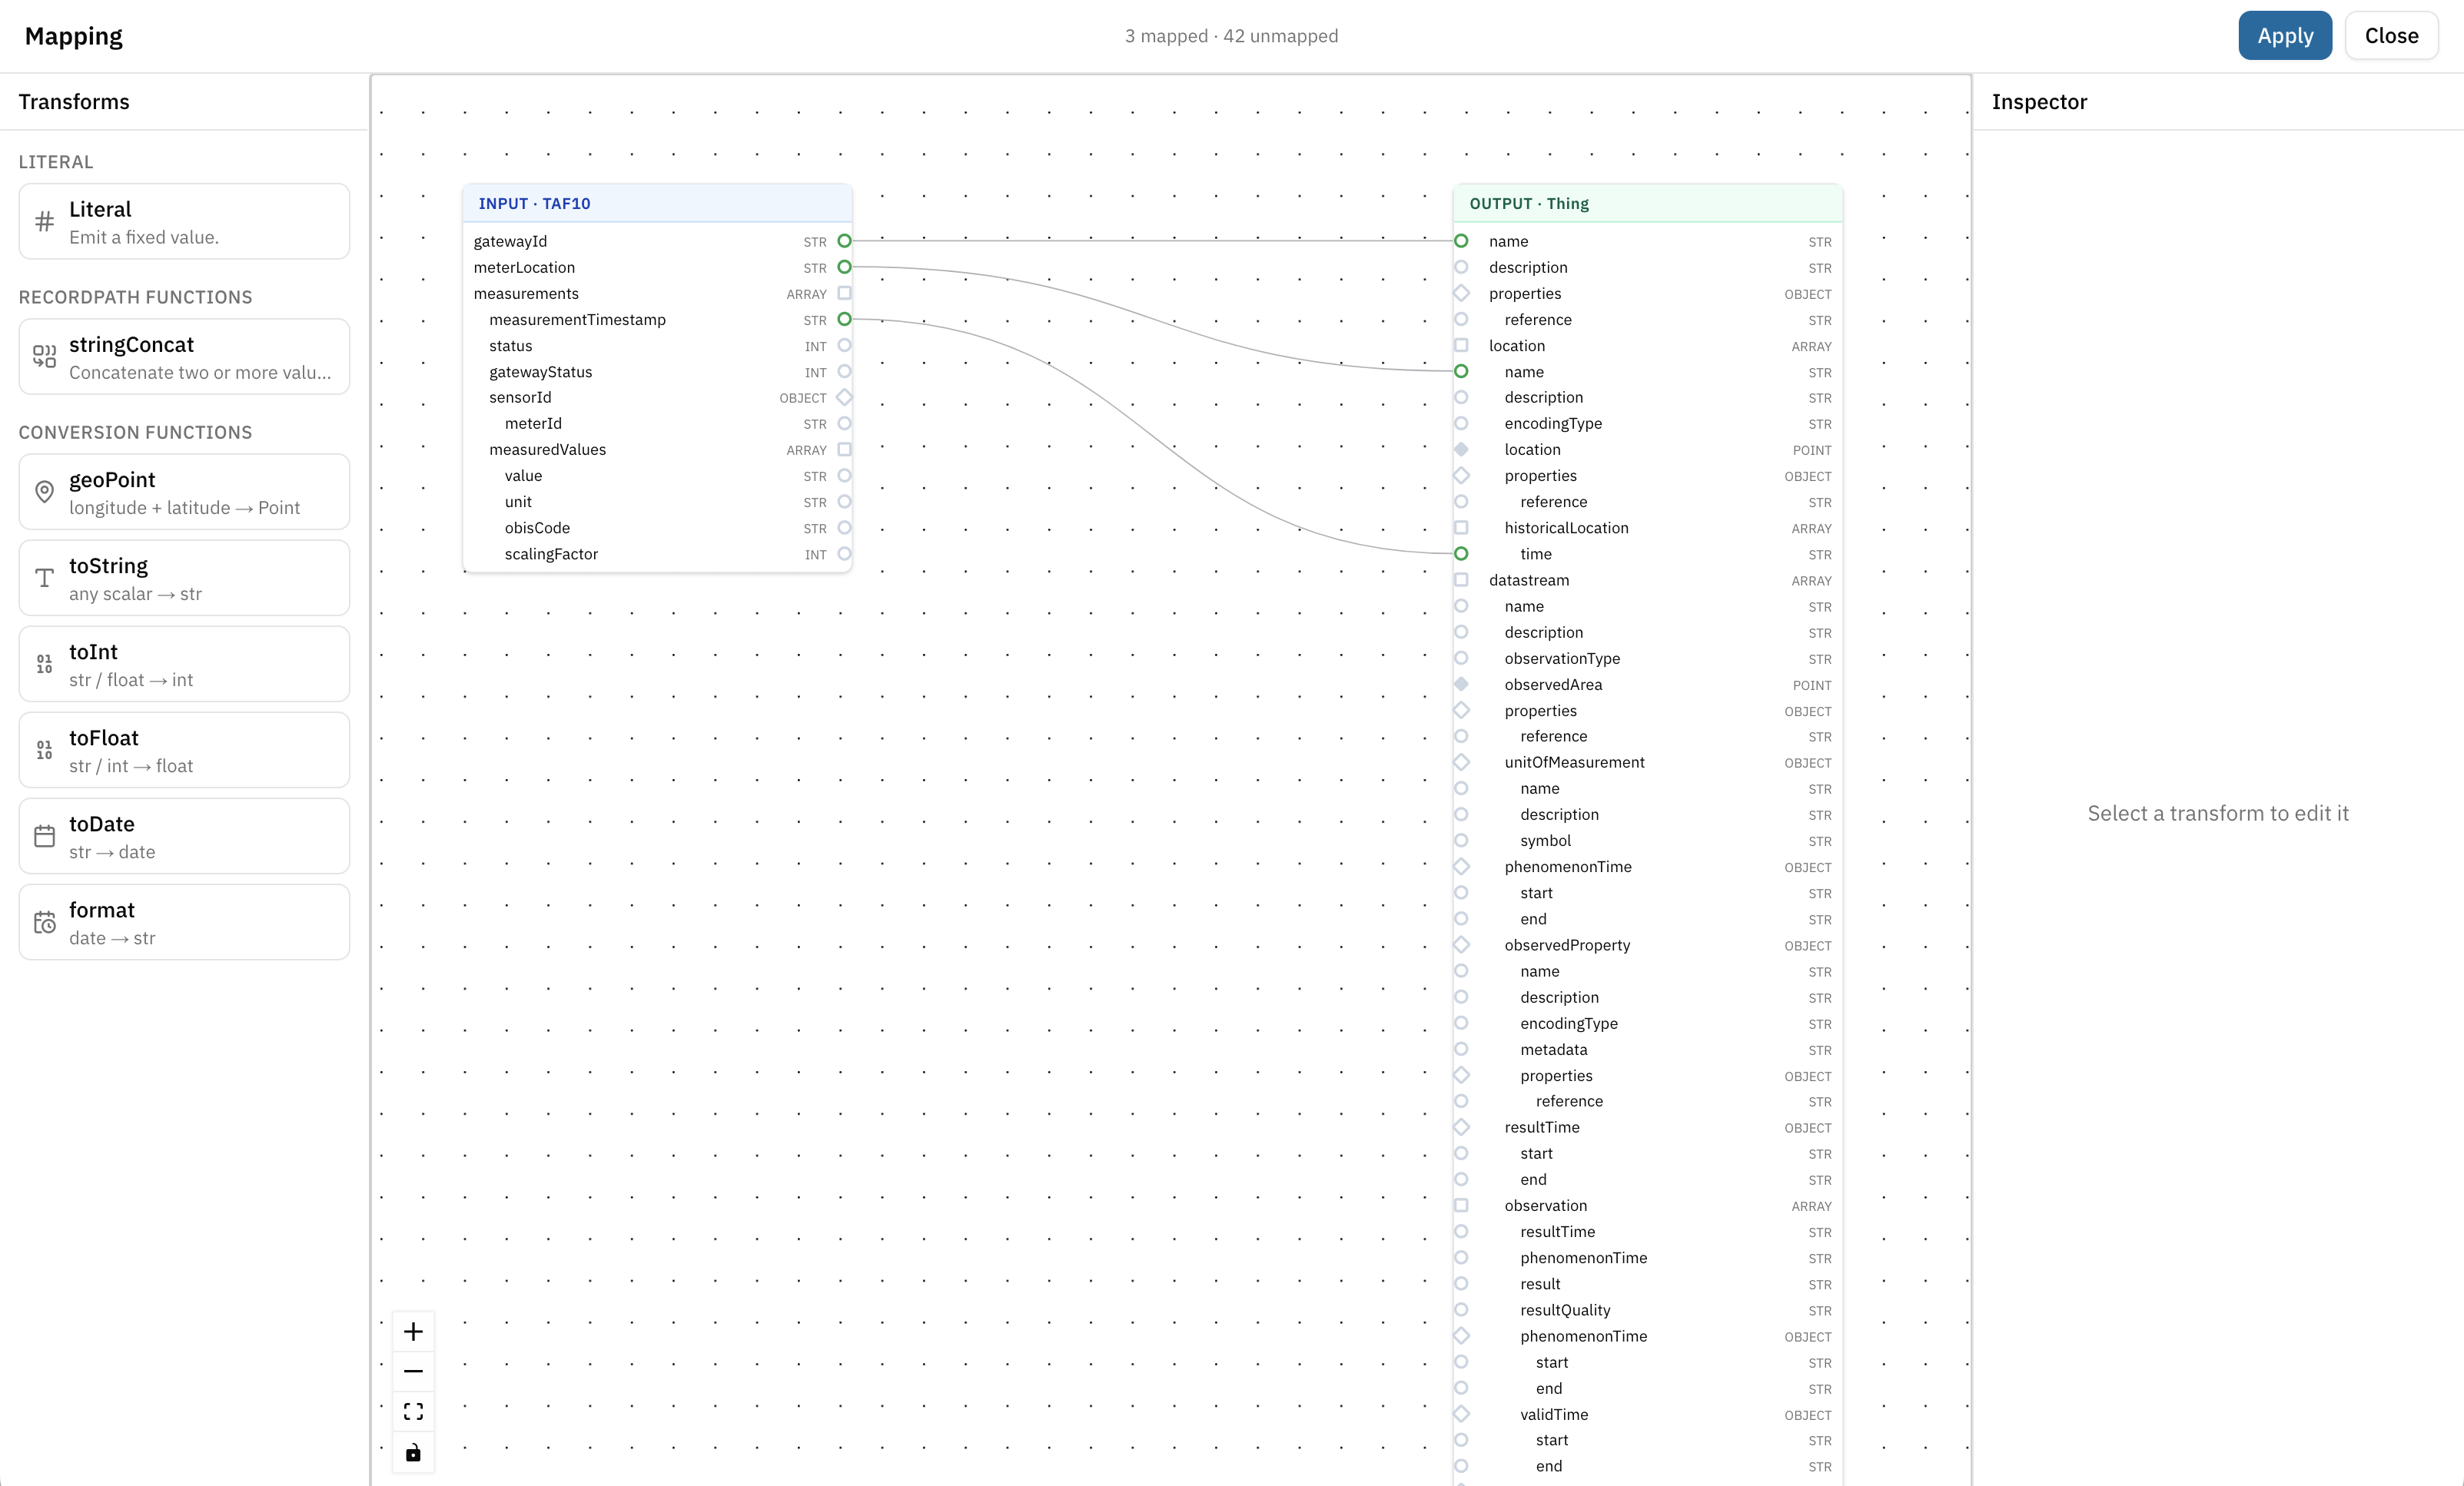
Before saving the Mapping:
- ensure all required target attributes are mapped
- verify that connected attributes use compatible data types
- resolve any validation issues
Once the Mapping passes validation:
- Hit Save
- Exit and Return to the Pipeline Canvas
- Connect all nodes to complete the pipeline
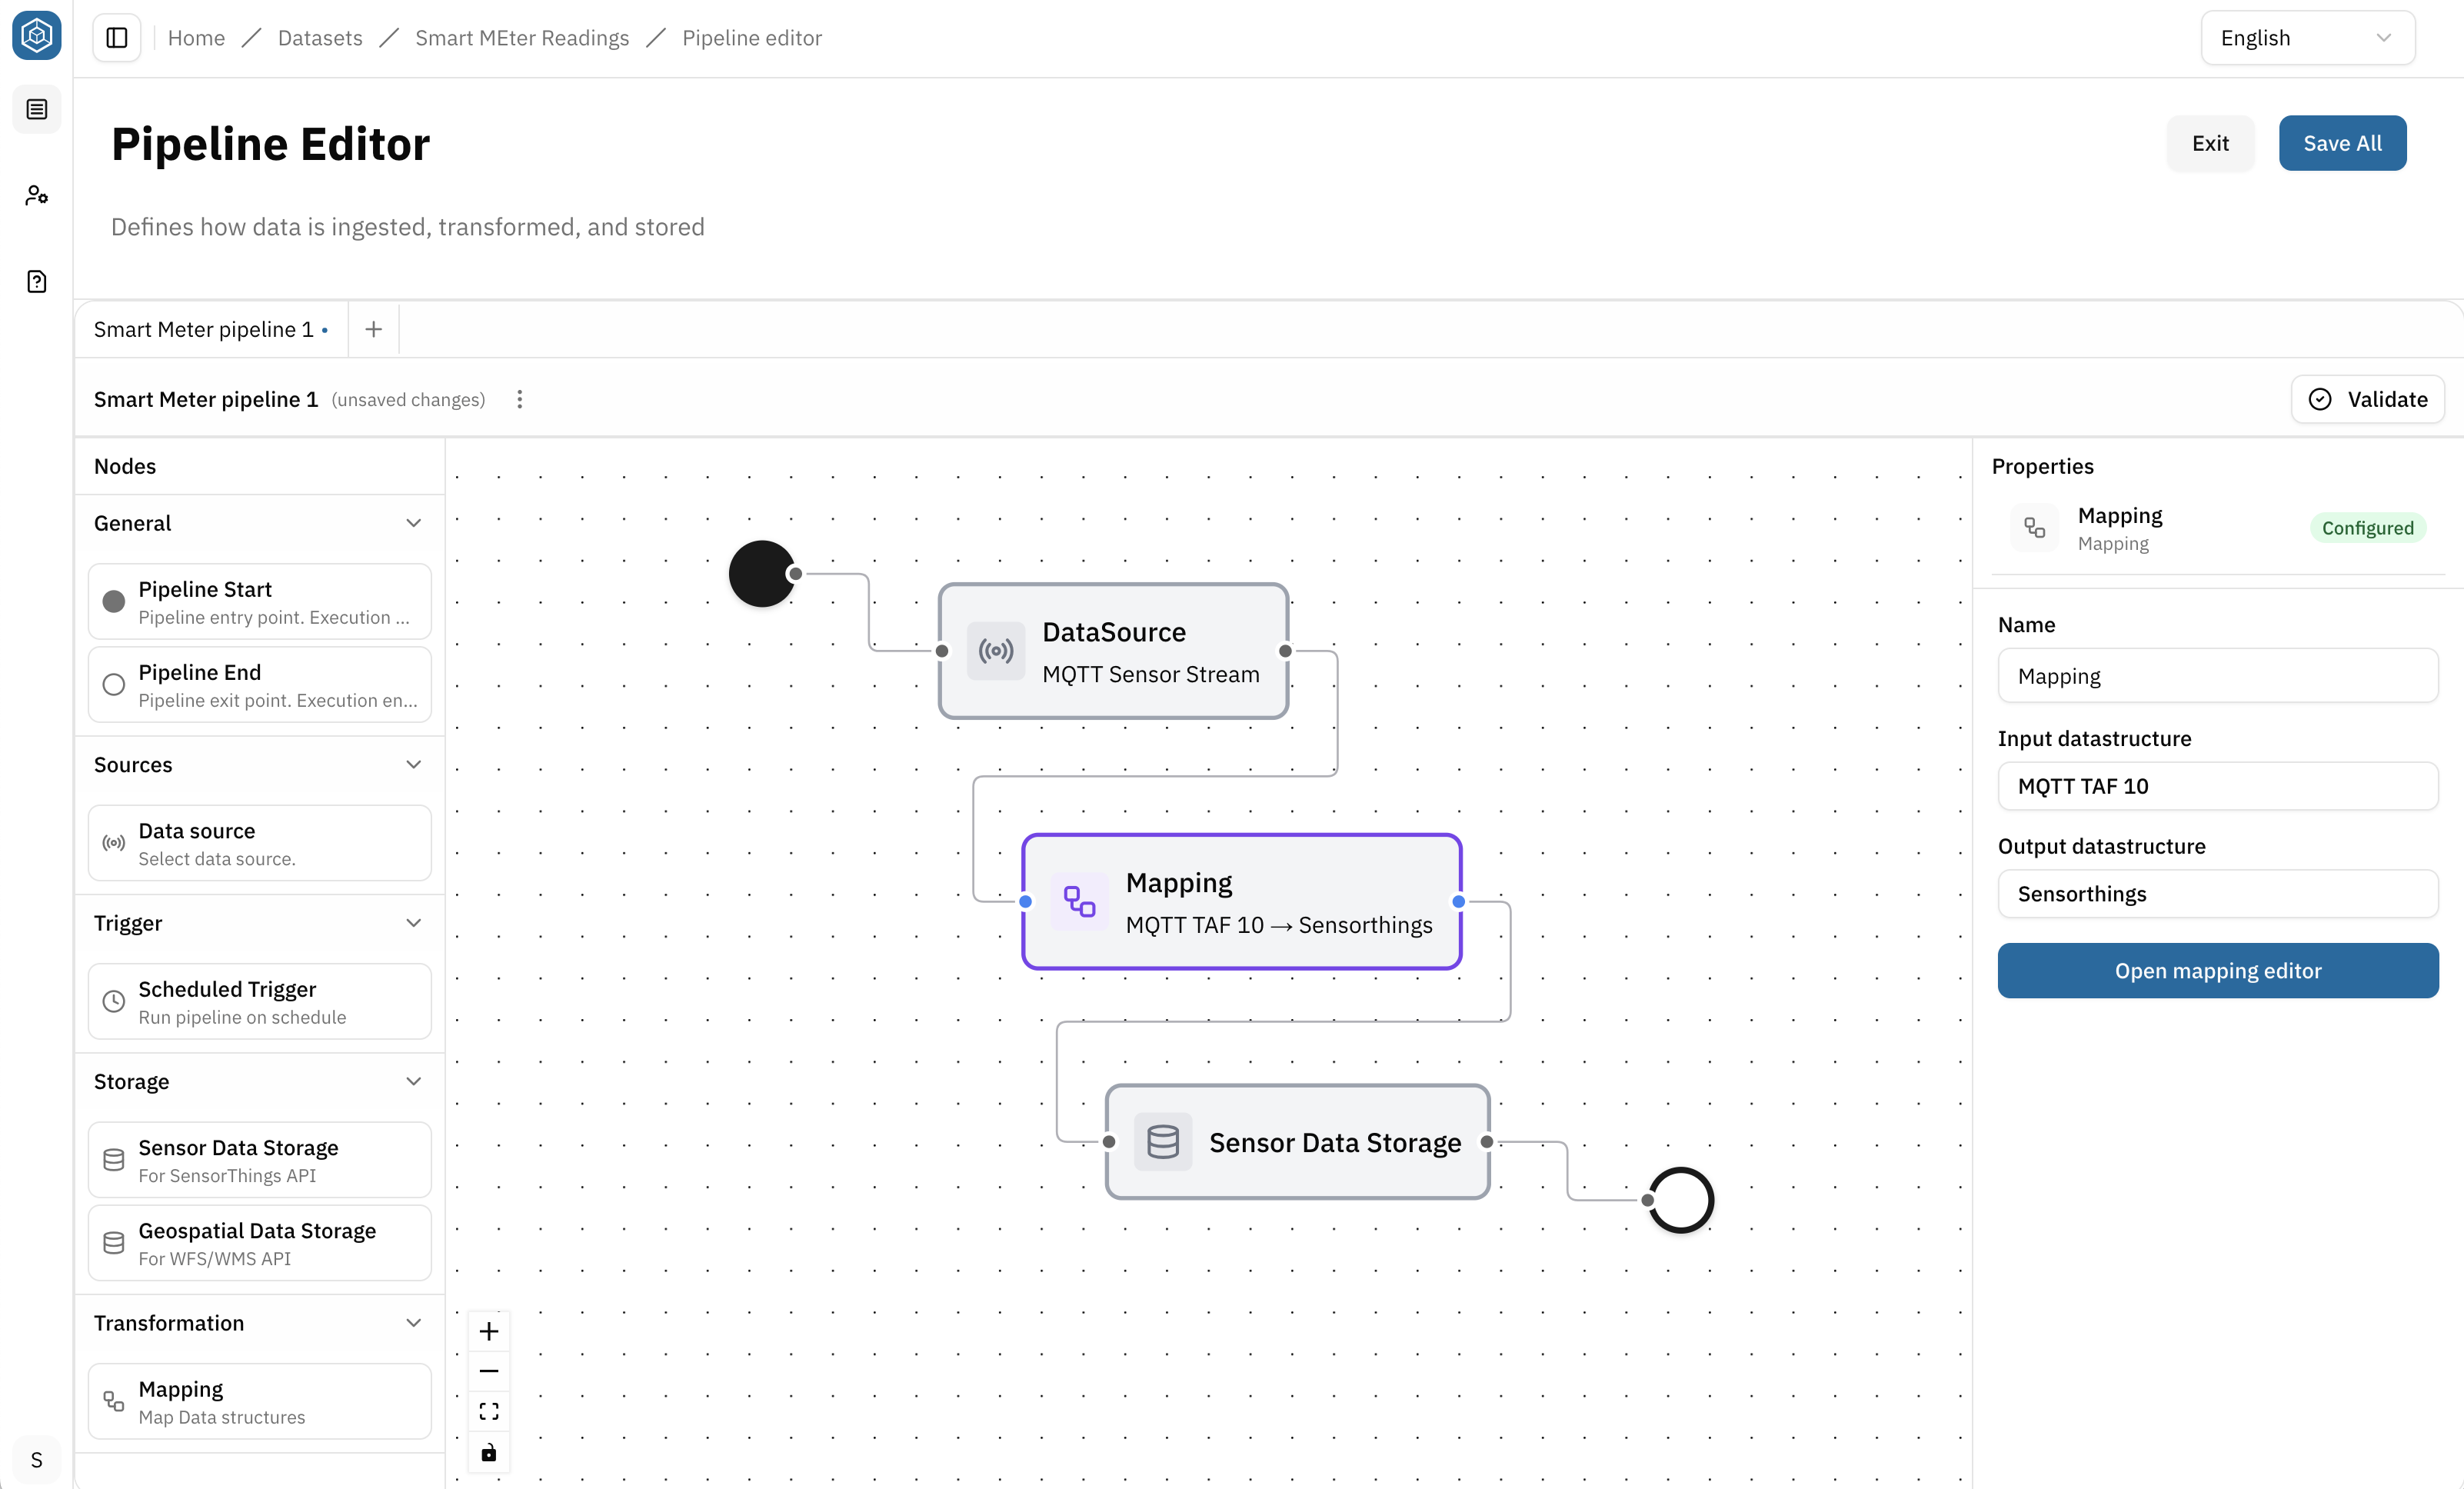
-
Click Validate to ensure that all nodes are correctly configured and connected
-
Fix any issues if needed, then hit Save and turn back to the detailview page of the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
This use case requires two pipelines within the same DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.:
- a master data pipeline
- a measurement data pipeline
Pipeline 1:
Start with the master data pipeline and follow the steps above. Use the configuration below as a reference.
Example pipeline name: Smart Meter Master Data
Pipeline structure: Flow start → Schedulded Trigger → Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. → Mapping → Storage → Flow end
Schedulded Trigger node: Defines when the pipeline runs. For example every 30 seconds:
*/30 * * * * *
Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. node: Assign the PostgreSQL Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. created earlier.
Mapping node: Transforms master data into SensorThings entities.
Sensor Data Storage node: Stores the transformed data in the SensorThings APISensorThings APIA standardized API based on the OGC SensorThings API specification for accessing time series and IoT data. It enables structured retrieval and management of observations and related entities. backend.
Pipeline 2:
Now, open a new pipeline tab and define the measurement data pipeline. Follow the same steps as above and use the configuration below as a reference.
Example pipeline name: Smart Meter Measurement
Pipeline structure: Flow start → Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. → Mapping → Storage → Flow end
Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. node: Assign the MQTT Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network. created earlier.
Mapping node: Transform incoming messages into Observations.
Sensor Data Storage node: Stores the transformed Observations in the SensorThings APISensorThings APIA standardized API based on the OGC SensorThings API specification for accessing time series and IoT data. It enables structured retrieval and management of observations and related entities. backend.
Step 3: Define an API
→ An API provides access to the Payload (actual Data) stored by a DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. and allows consumers to retrieve it through a dedicated API URL.
Once a valid Pipeline exists and data is persisted using a Storage node, an API can be created for the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions..
To create an API
- Open the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
- Navigate to Dataflow section → APIs
- Select Add API
- Choose an API type
- A form opens: Enter Title and Description (optional)
- Hit Save
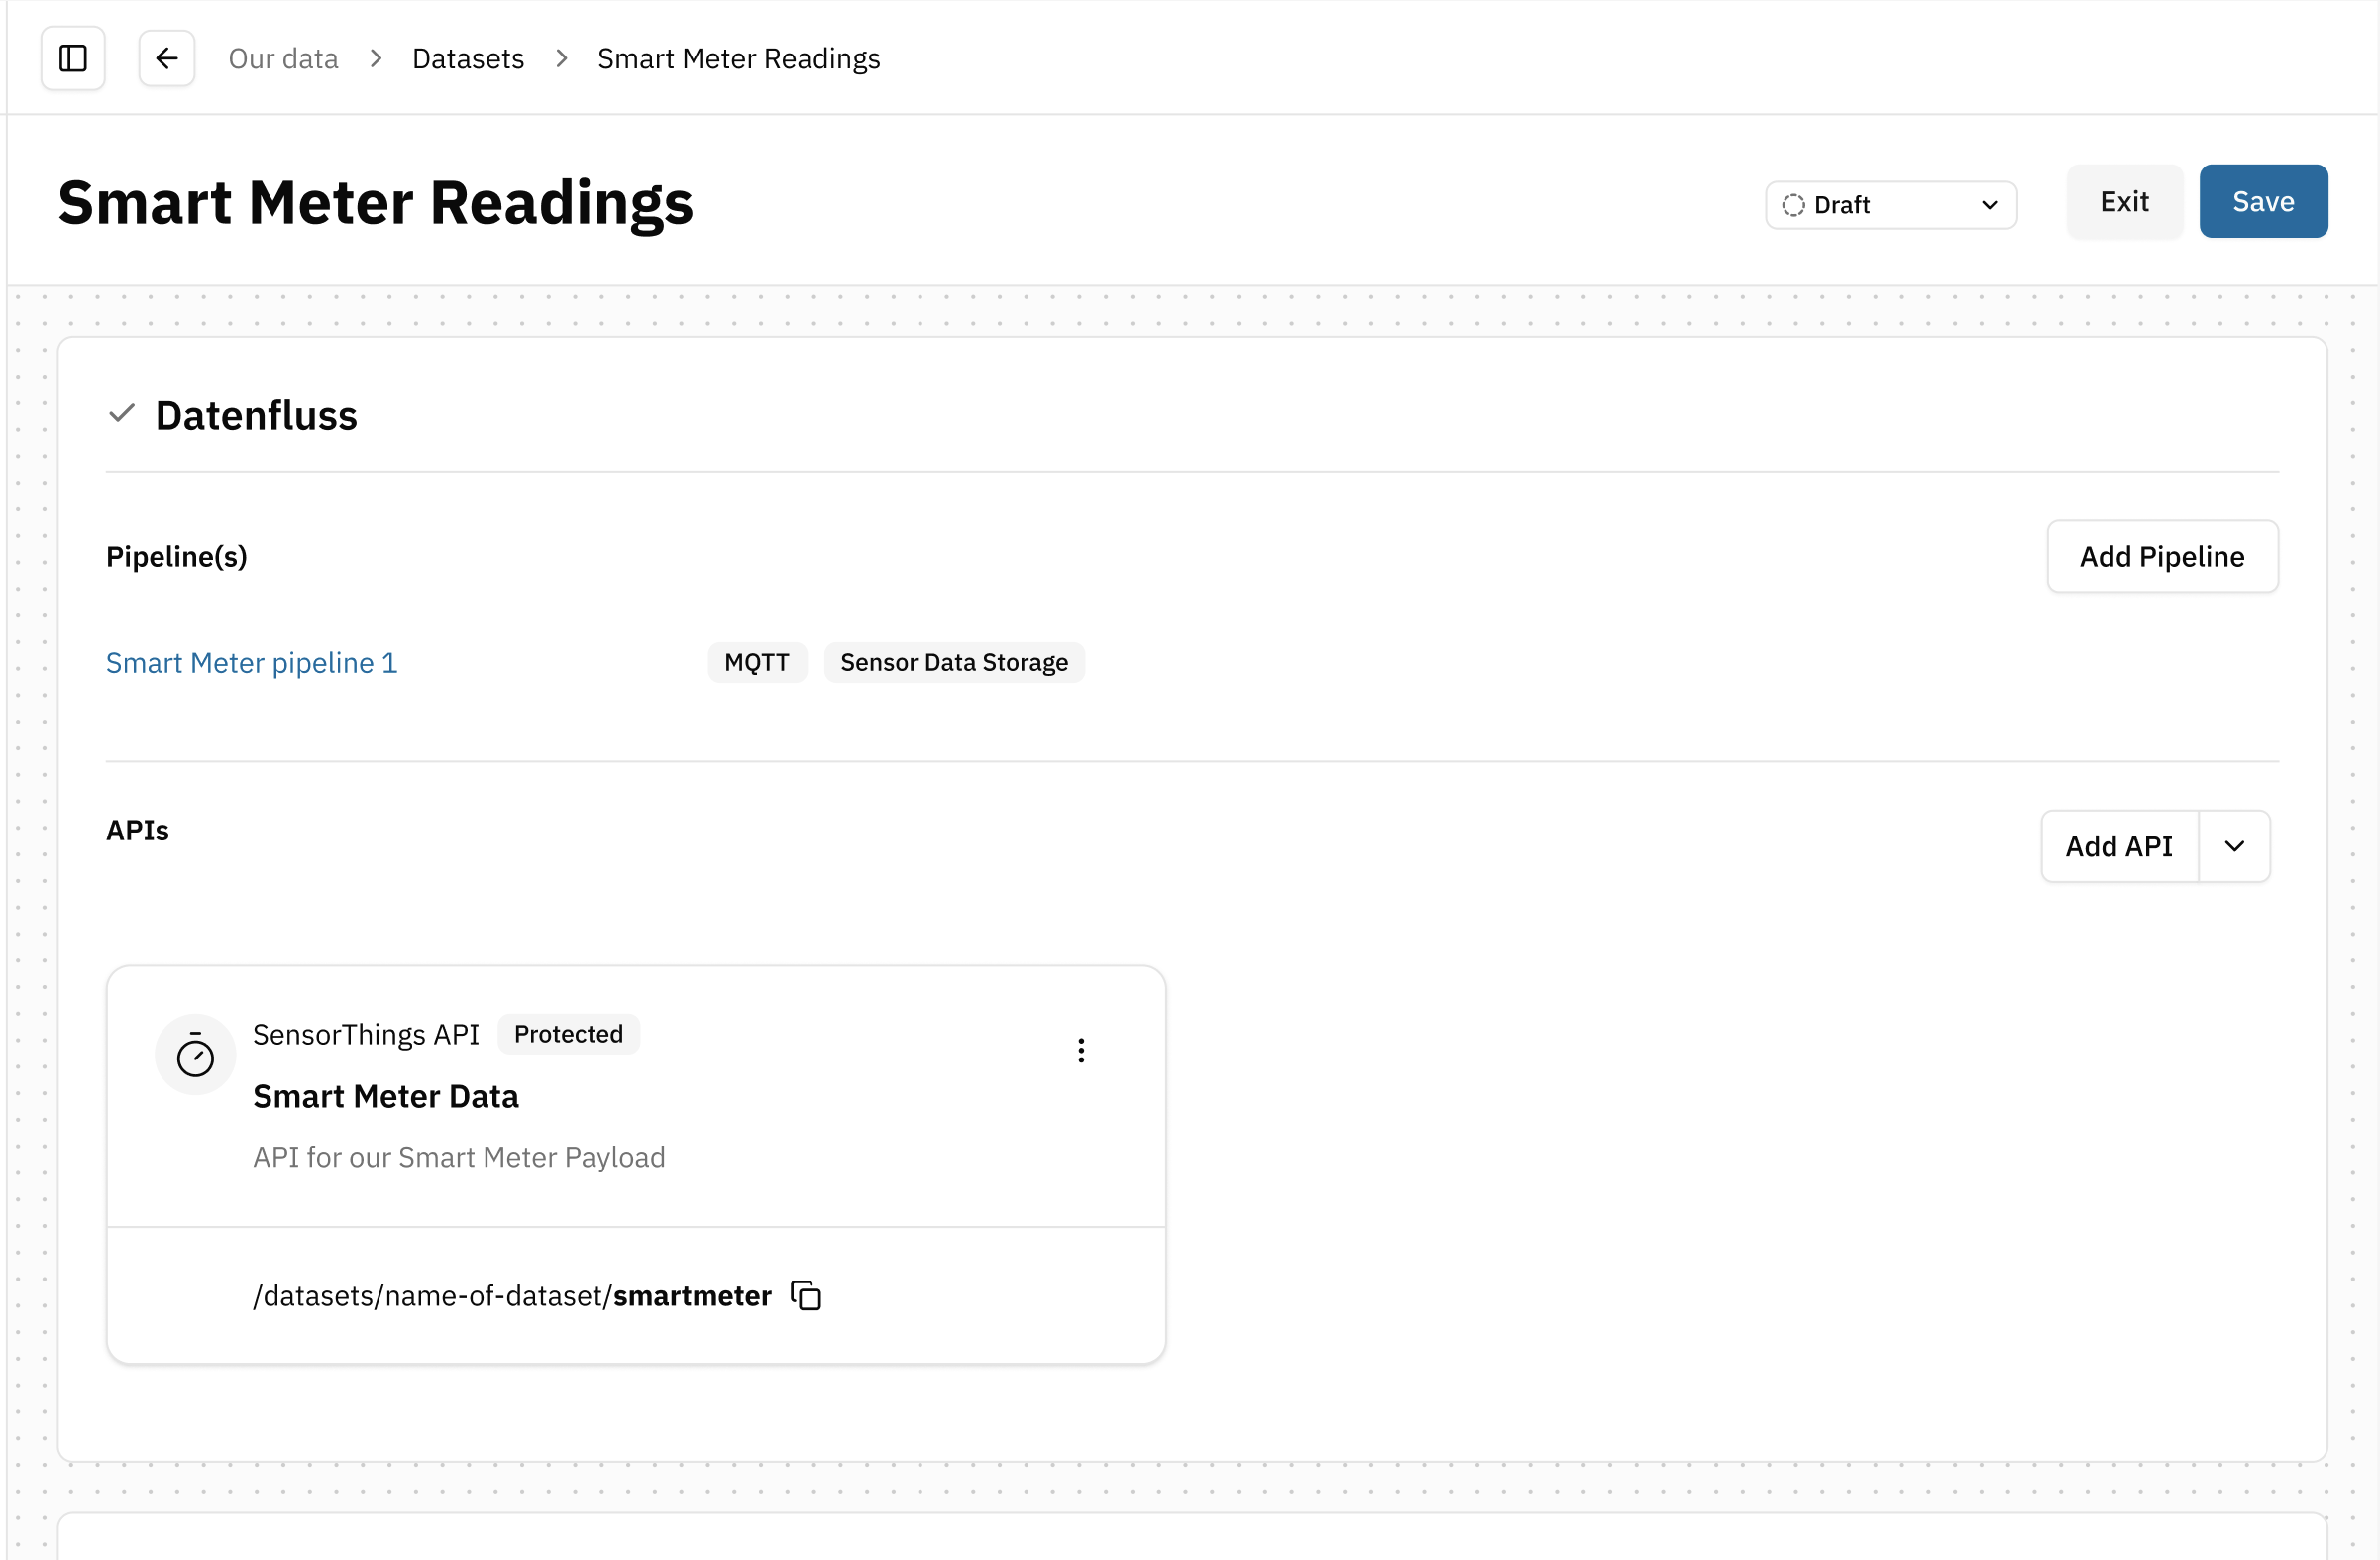
Available API types depend on the Storage nodes used in the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.'s Pipelines. An API type can only be selected if data is stored using a compatible Storage node.
Examples: Sensor Data Storage → SensorThings APISensorThings APIA standardized API based on the OGC SensorThings API specification for accessing time series and IoT data. It enables structured retrieval and management of observations and related entities., Geospatial Data Storage → WFS/WMS APIWFS/WMS APIA standardized geospatial API that makes spatial data available through Web Feature Service (WFS) and Web Map Service (WMS). It enables applications to access geographic features and map visualizations from a Dataset. Both are standards of the Open Geospatial Consortium (OGC).
After closing the form, a new API tile is created in the APIs section of the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. overview.
The tile displays:
- API name
- type
- optional description
- API URL
→ The API URL can be copied and shared with consumers.
Edit the API:
- Select the tile to reopen the API configuration form and update its settings
Delete the API:
- open the actions menu (⋯) on the API tile and select Delete
For this use case, select: SensorThings APISensorThings APIA standardized API based on the OGC SensorThings API specification for accessing time series and IoT data. It enables structured retrieval and management of observations and related entities. – Time-series Data. This API type provides access to the time-series data persisted by the Pipeline in the Sensor Data Storage node.
Step 4: Open and manage access permissions
Permissions can be granted at different levels:
- Platform-wide through Data Roles assigned in TenantTenantAn isolated organizational partition that owns Data pools, Datasets, Users, Groups, and Roles. All access rules exist within their Tenant, and the Tenant is the widest Scope of a Role. Currently, one Tenant corresponds to the Platform. Management
- Through permission inheritance from the assigned Data poolData poolA governed, centralized collection of Datasets that are managed together within the Platform. It provides a shared place to organize, discover, and access data, including associated metadata, ownership, and access permissions. With Data pools users can cluster their Datasets according to their organizational structure (e.g., by Departments, Offices).
- Directly on the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
Configure permissions on the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. only when DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.-specific access is required.
- Click Edit Groups and Roles in the section Access Management
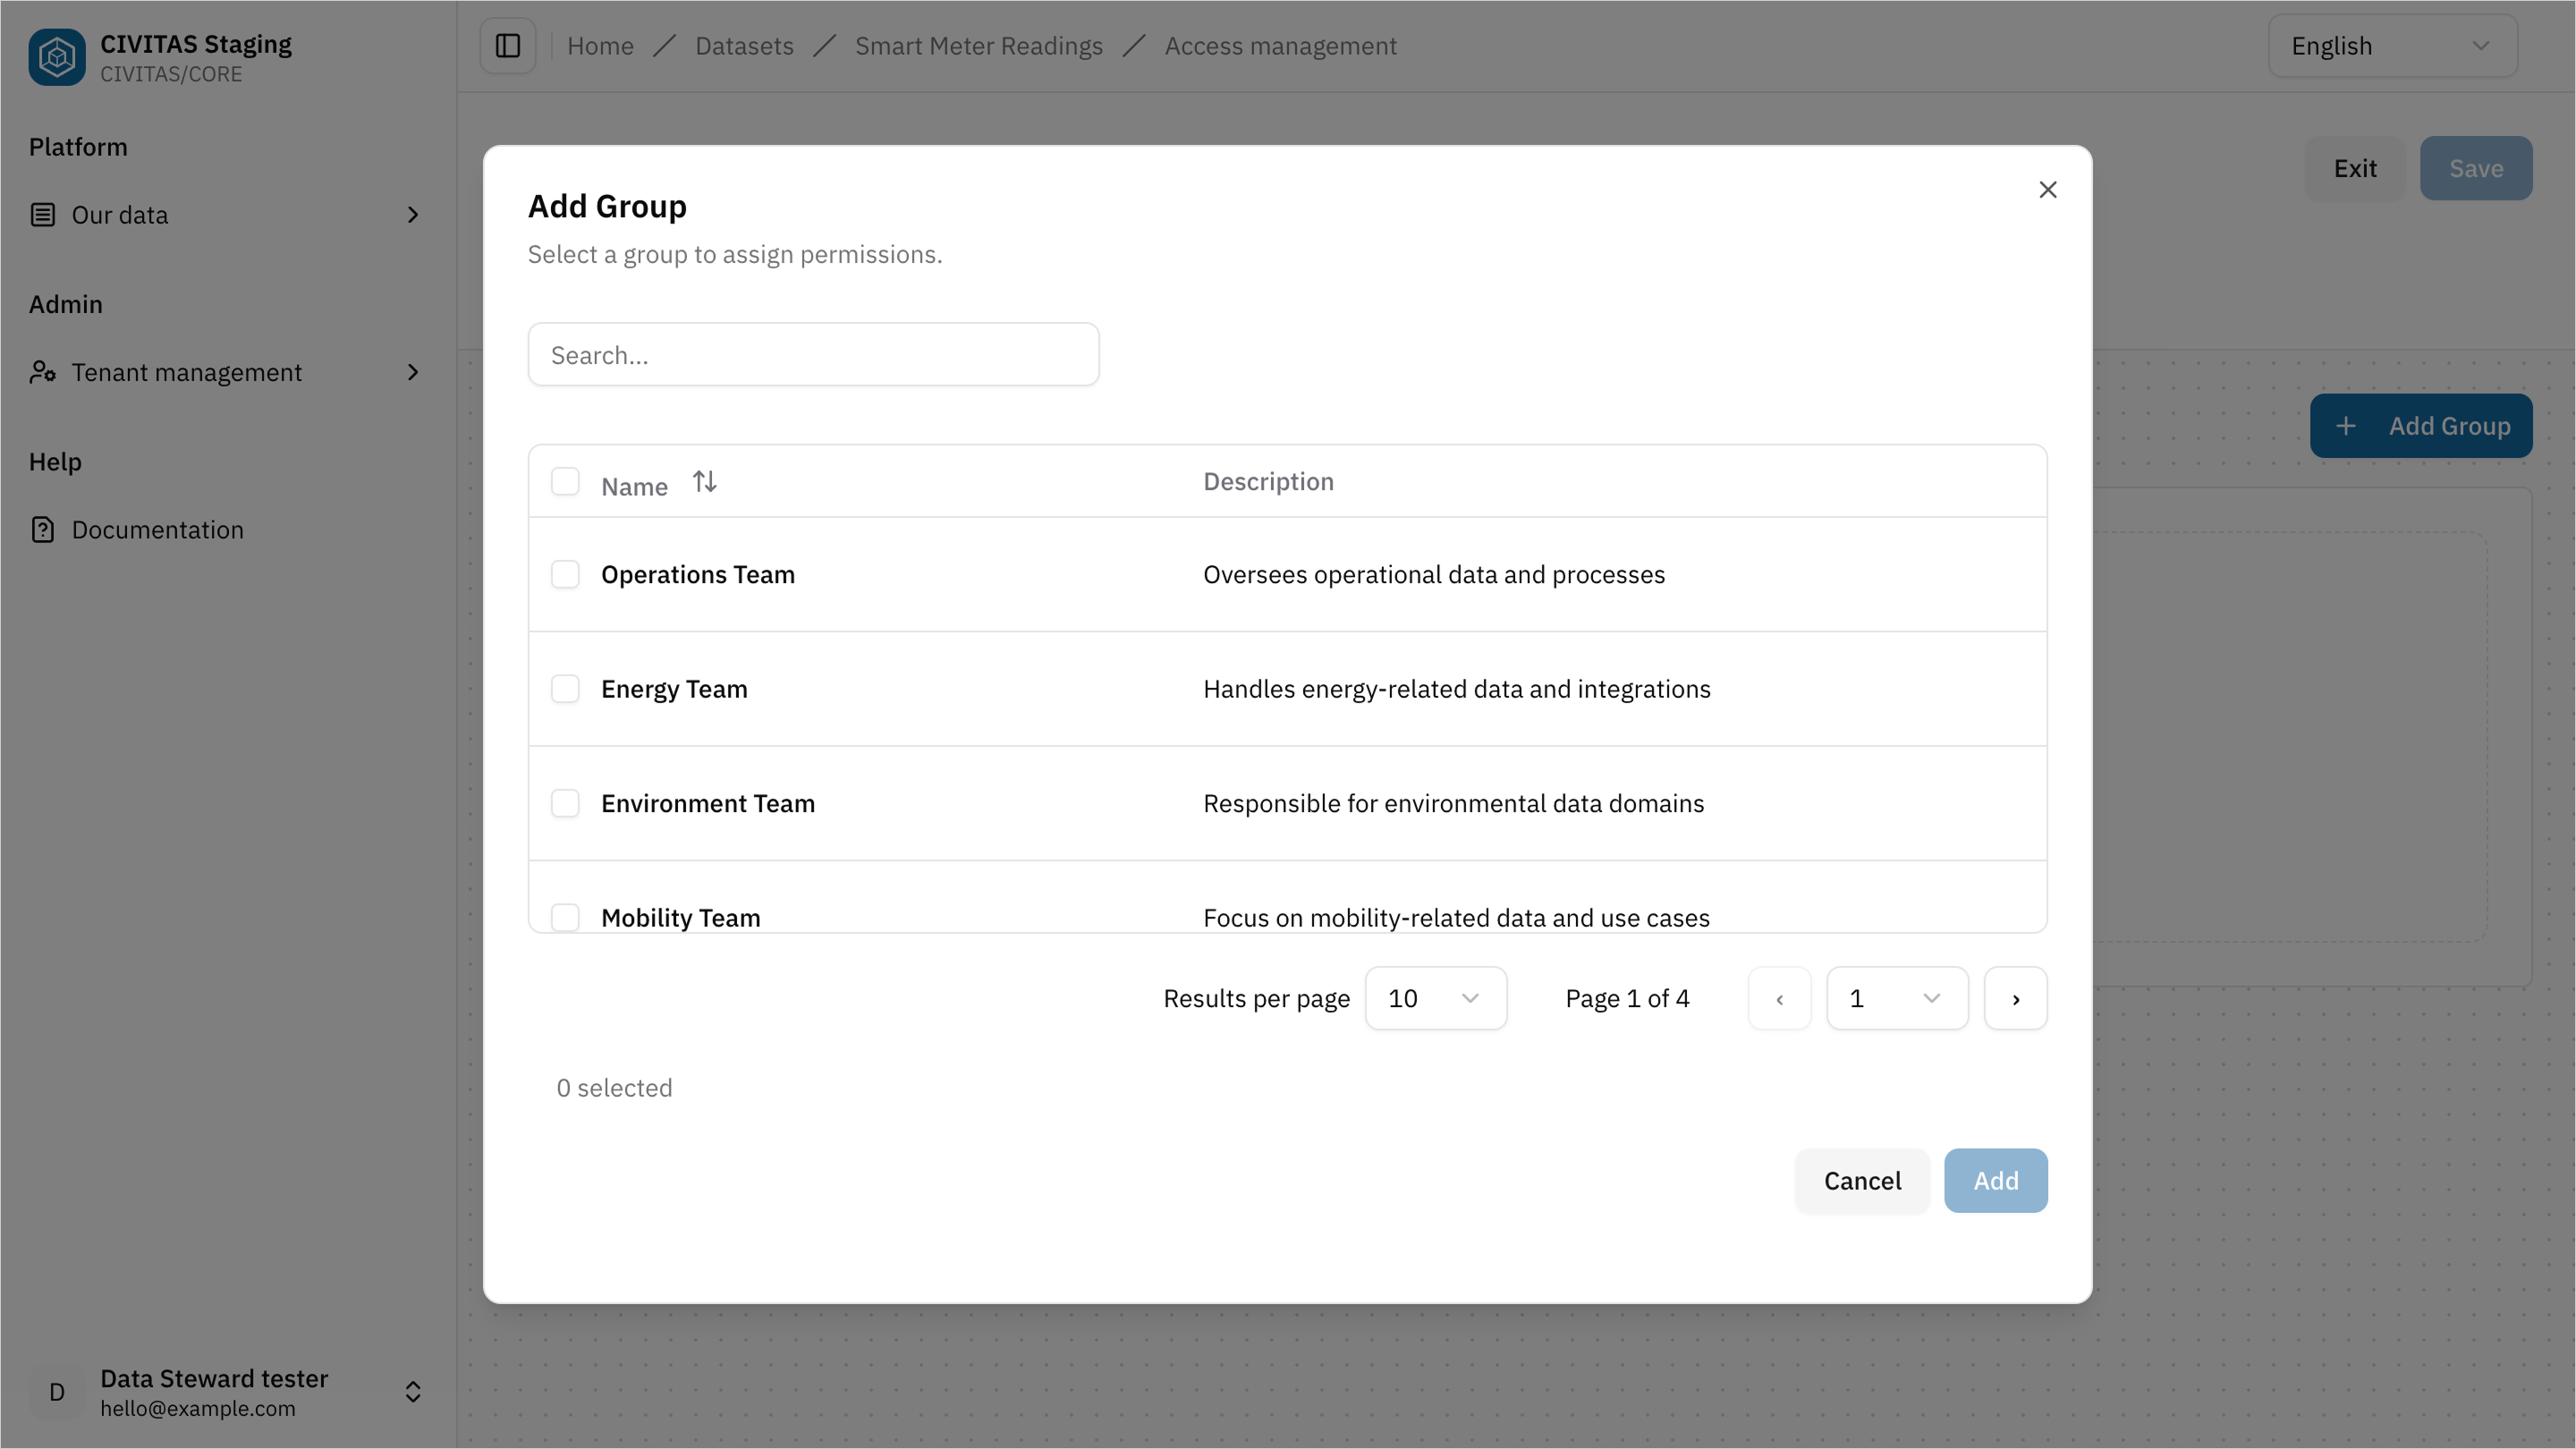
- Add a Group
- Assign a Role to the Group
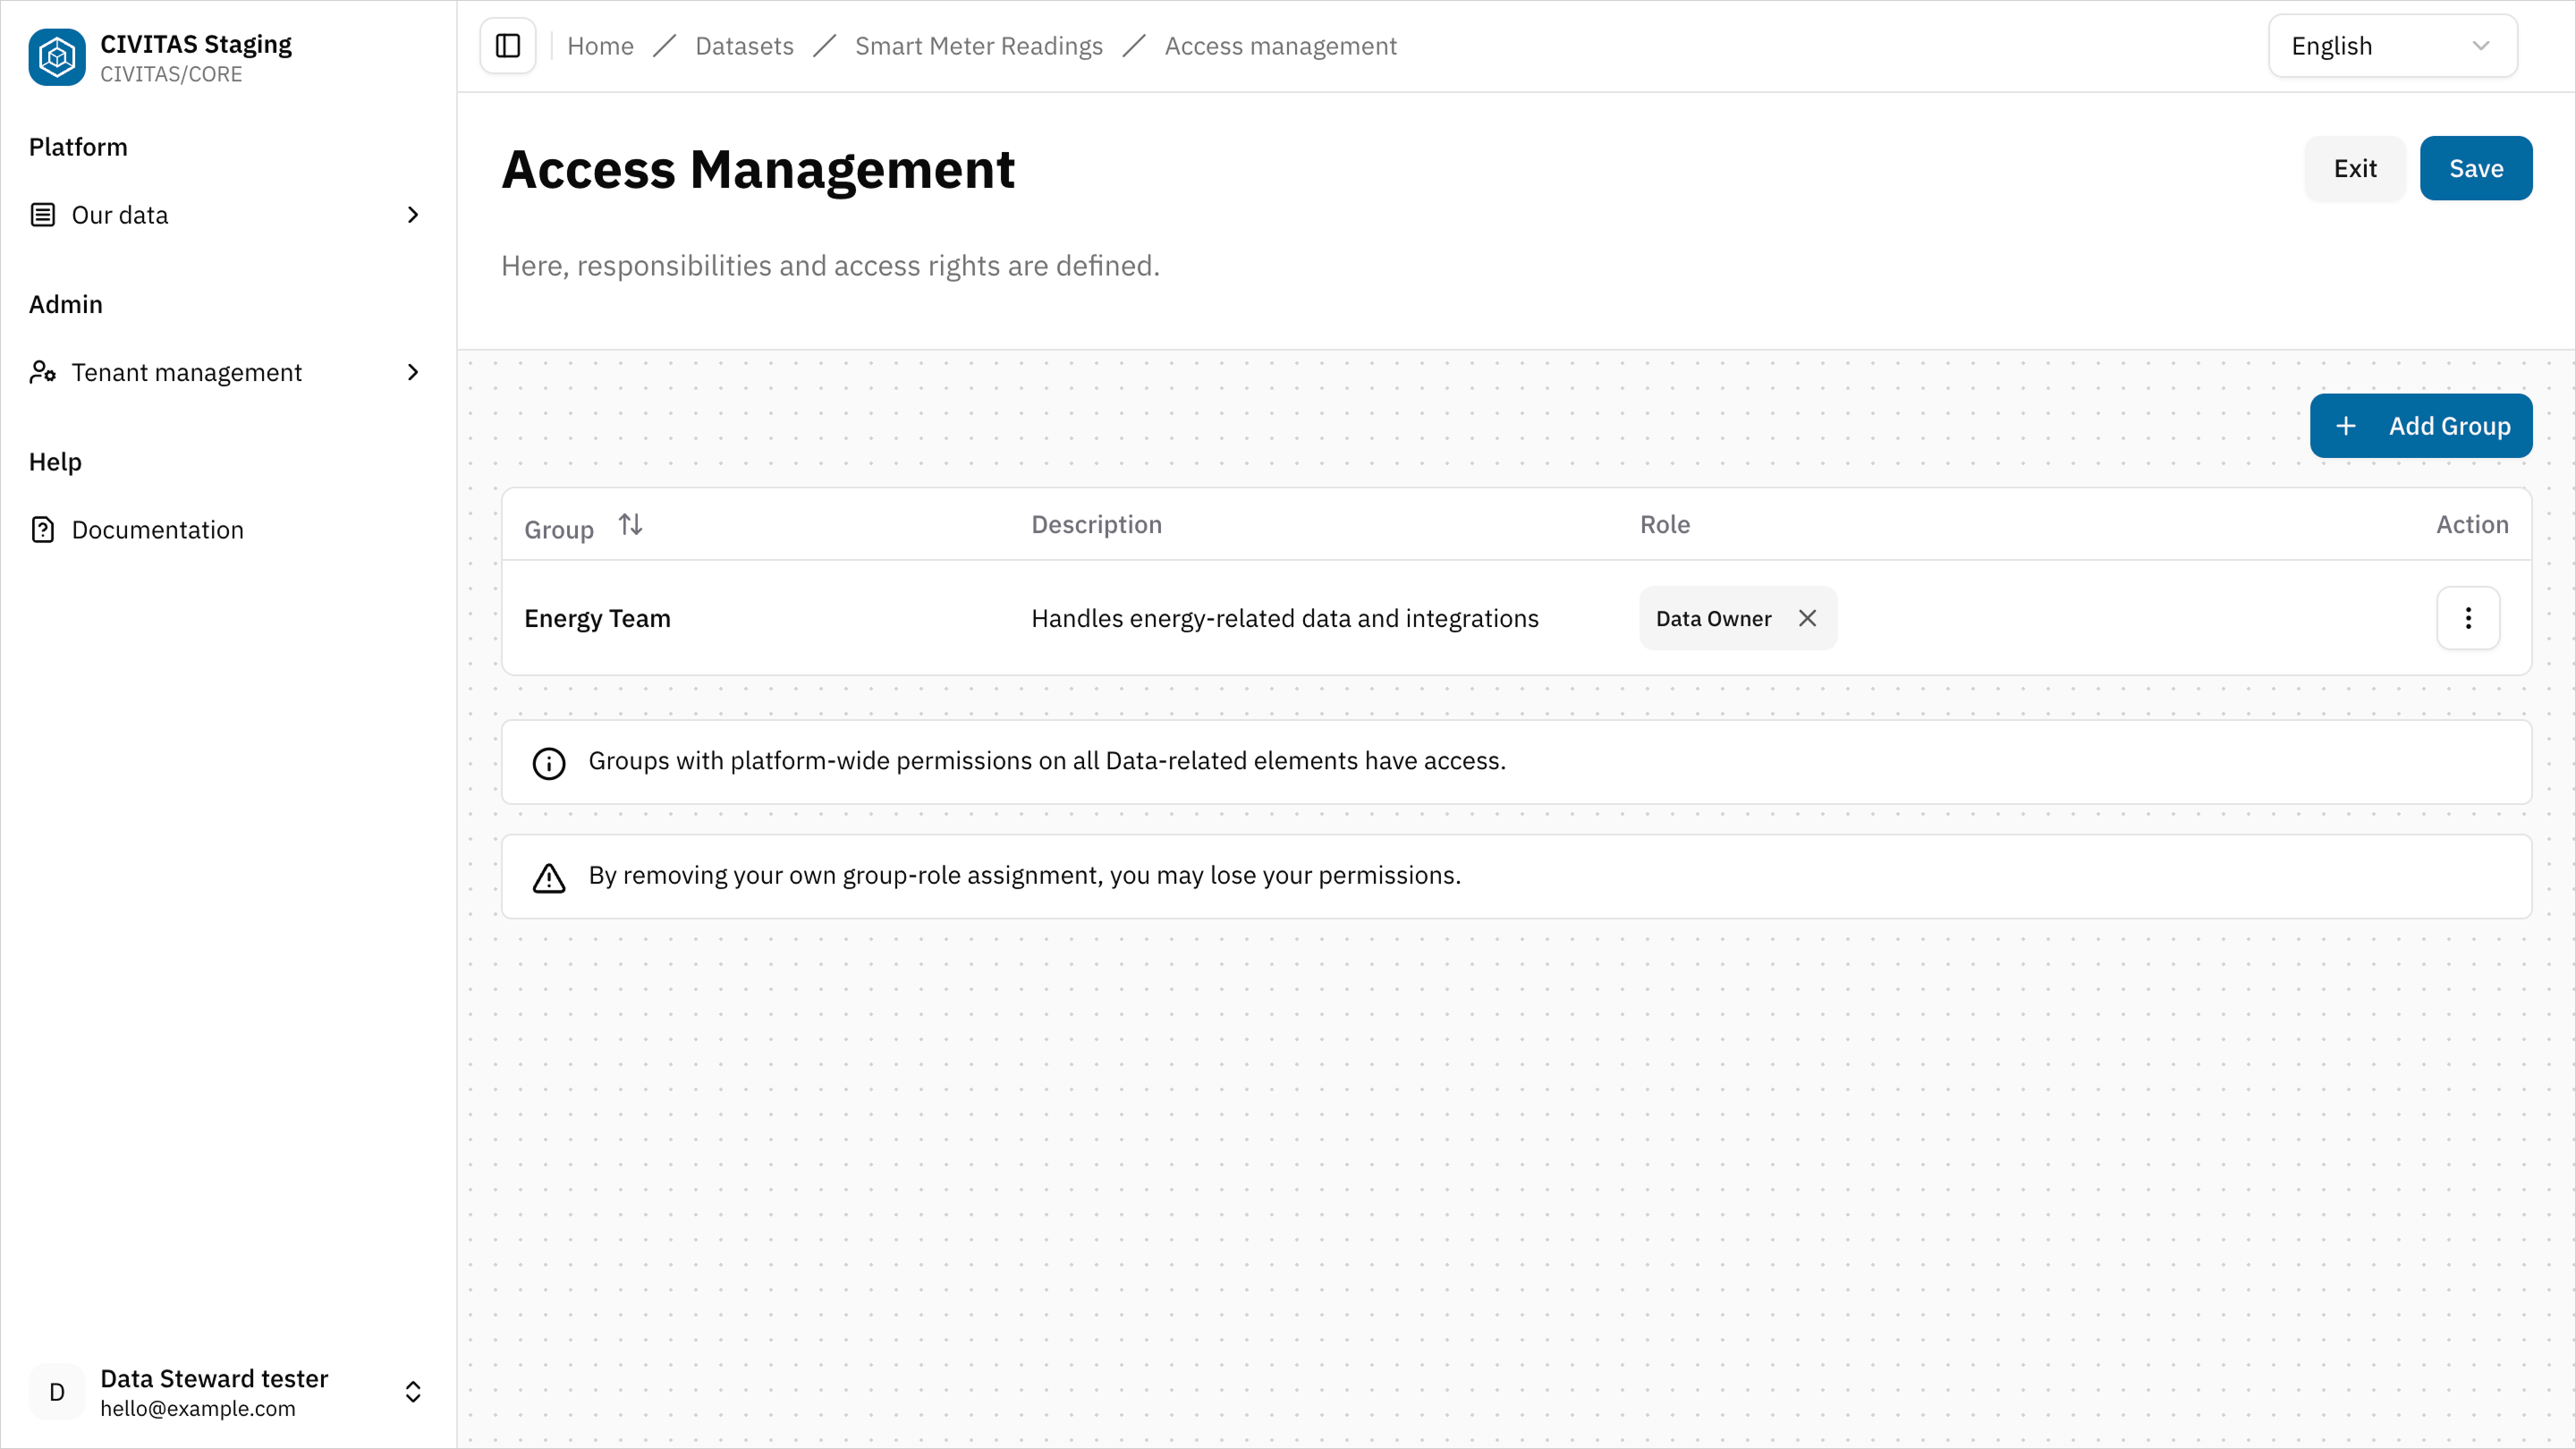
- Repeat these steps to add more Groups and Roles
- Hit Save and Turn back to the detail view of the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
Step 5: Mark the Dataset as ready
→ Setting the status to Ready signals that the creation phase of the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. is complete. The DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. is now prepared for review.
- Change the Status to Ready
- Contact a Data Owner or Data Gatekeeper to review and release it.
You can:
- share a direct link to the Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network.
- or provide the name of the Data sourceData sourceA data-related element that represents the origin of data. It defines how data is connected, accessed, and ingested into the Platform, such as an external database or sensor network.
Pipelines start processing data only after the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. has been released and its status has been changed to Available.
Outcome
The DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. is Ready and can now be reviewed and released.
Summary
You have successfully:
- Created a DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
- Defined a Pipeline
- Defined an API
- Configured access permissions
- Marked the DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions. as Ready
Next
You have completed the creation phase of your DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.. In the next guide, you will:
- review a DatasetDatasetA data-related element that contains processed data and makes it available for consumption. A Dataset is populated via Pipelines and carries Metadata and access permissions.
- release it for use
- make it available to others
→ Continue with Release data